To run survival analysis basics you need two variables, one estimating method, and software that does the arithmetic for you: a time variable recording how long you followed each participant, and a status variable recording whether the event you care about actually happened. Everything below builds on that pair.
The payoff is that you keep the people whose event never occurred during the study instead of throwing them away. SPSS takes you through it with menu paths that are hard to get wrong. R gives you more control once you understand what the output means.
Updated for 2026.
Table of Contents
- 1What You Need
- 2Step-by-Step
- 3How to Prepare Time-to-Event Data
- 4How to Estimate Kaplan-Meier Survival Probabilities
- 5How to Compare Survival Between Groups
- 6How to Run a Cox Regression in SPSS and R
- 7Common Mistakes
- 8Frequently Asked Questions
- 9What is the Kaplan-Meier method used for in survival analysis?
- 10How do I interpret the 95% confidence interval of a hazard ratio?
- 11What is right censoring, and why does it matter?
- 12When should I use Cox regression instead of the log-rank test?
- 13Why use survival analysis instead of a chi-square test?
- 14How do you check the proportional hazards assumption?
- 15Conclusion
What You Need
Before you open any software, write down two things in one sentence: what counts as the event, and where the clock starts. A relapse, a death, a machine breakdown, a subscription cancellation. Time origin might be diagnosis date, purchase date, or the date of a repair visit. Survival analysis only makes sense once those are pinned down, because a different event definition gives you a different curve from the same data.
Then check the data. You need exactly two core variables per participant. Time can be in any consistent unit, usually days, weeks, or months. Status is coded 1 when the event happened and 0 when the observation was censored. Different programs default to opposite conventions, so confirm this before you run anything rather than after.
This is where survival methods differ from ordinary analysis. If you measure a final blood pressure reading or an end-of-study score, a t-test or linear regression fits. Survival methods exist because participants leave studies at different times, and you only observe the event for some of them. Dropping censored cases discards their follow-up entirely and biases the estimate, which is the whole reason this family of methods was built.
Three assumptions run through everything below. Time must be measured the same way for everyone. Censoring must be independent of the event, meaning people drop out for reasons unrelated to the outcome. And a Cox model needs one more: the ratio of hazards between groups stays roughly constant across the follow-up period.
On software, SPSS is the faster route for a click-by-click walkthrough with tidy Output Viewer tables. R is better once you want custom plots, automated checks, or reproducible scripts. Forum threads on where to start with survival analysis keep repeating the same advice: get comfortable with regression and maximum likelihood first, because the Cox model output is much easier to read once likelihood thinking is familiar.
Step-by-Step
How to run survival analysis basics in either program comes down to the same sequence: get the time and status variables right, estimate the Kaplan-Meier curve, compare groups, fit a Cox model when you need adjustment for other variables, and write the results in words. Work through them in that order and each output makes sense of the next one.
How to Prepare Time-to-Event Data
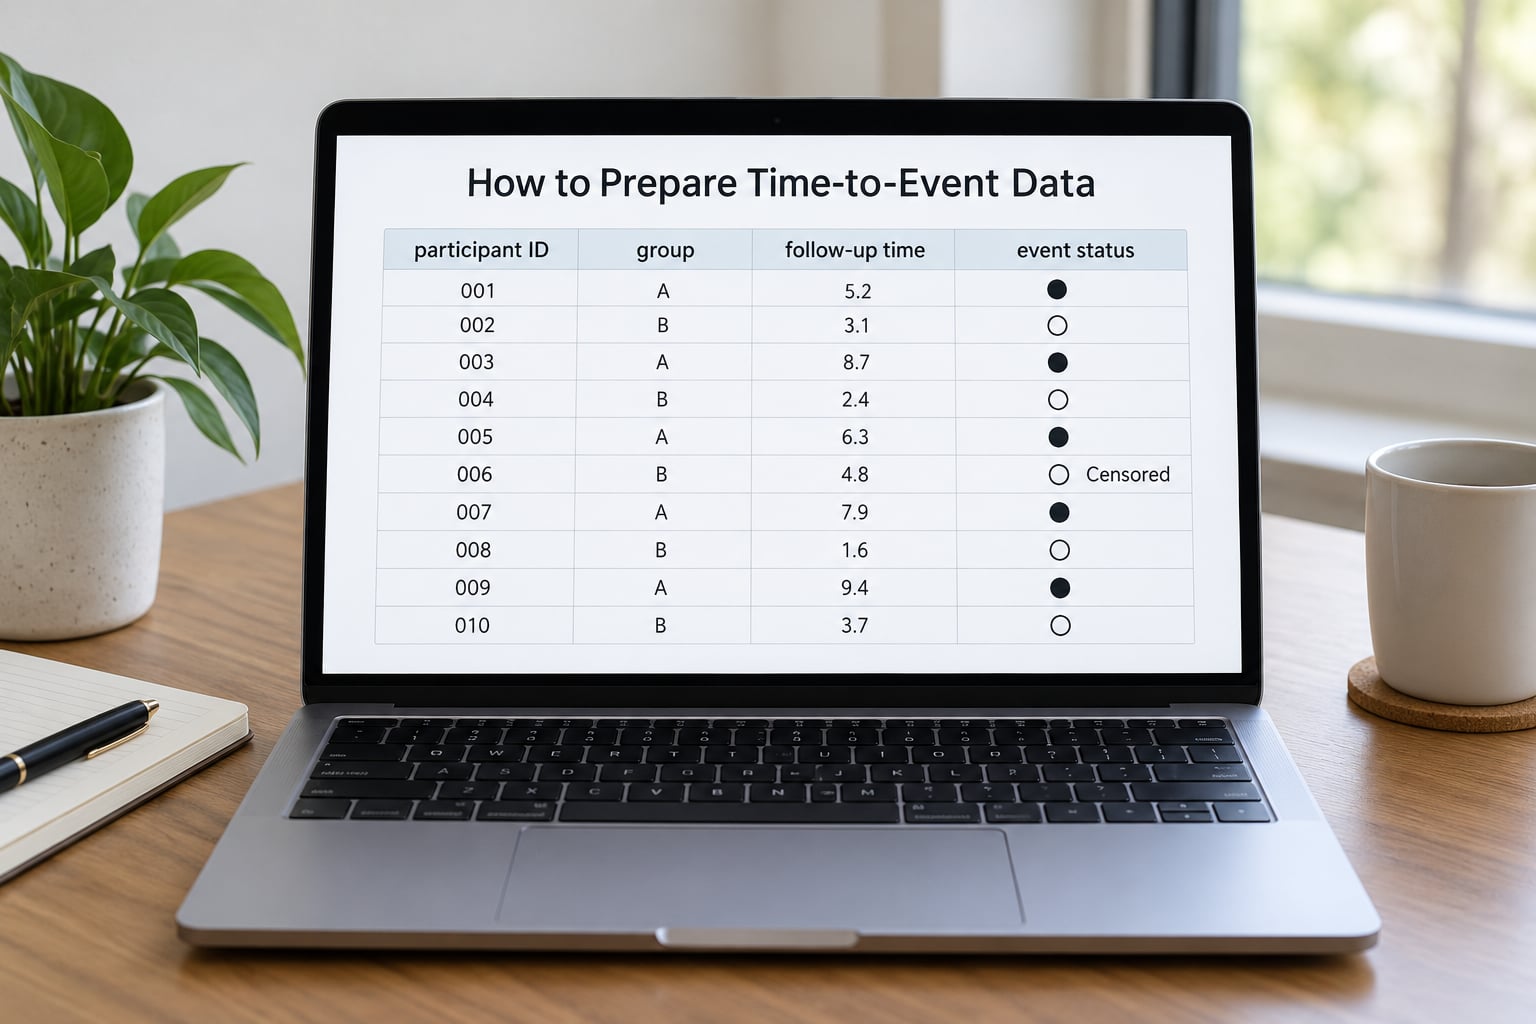
One row per participant, no wide format. Do not collapse repeated visits into a single line unless you are deliberately building a counting-process dataset, which is a different exercise. Keep the raw follow-up time even for censored cases, because a participant who stayed event-free for 18 months contributes real information.
Censoring simply means the event was never observed for that participant. Right censoring is the normal case: the study or the observation window ended while the person was still event-free. Backward censoring, where the event time falls before the point where observation started, is rarer and usually comes up in retrospective chart reviews.
Check the coding in both programs before you analyse anything. In SPSS the survival dialogs ask whether the event is the lower or the higher value on the status variable. In R the conventional argument is event = status, with 1 meaning the event occurred. Reverse either one and every number inverts without any error message to warn you.
Here is the small dataset used throughout this guide. Ten participants, seven observed events, three censored, one row each.
| ID | Group | Time (months) | Status | Outcome |
|---|---|---|---|---|
| 1 | A | 2 | 1 | Event |
| 2 | A | 3 | 1 | Event |
| 3 | A | 4 | 1 | Event |
| 4 | A | 5 | 1 | Event |
| 5 | A | 6 | 1 | Event |
| 6 | B | 7 | 1 | Event |
| 7 | B | 8 | 1 | Event |
| 8 | B | 10 | 0 | Censored |
| 9 | B | 12 | 0 | Censored |
| 10 | B | 14 | 0 | Censored |
Missing values need a decision rather than a default. If follow-up time is missing, that case cannot contribute and most software drops it silently. If a covariate is missing, Cox regression in R uses complete cases unless you impute; researchers posting on Cross Validated recommend multiple imputation and summarising results in a way that carries the imputation variance through to the final estimates.
How to Estimate Kaplan-Meier Survival Probabilities
The Kaplan-Meier estimator multiplies the conditional probability of surviving past each event time, which produces a step function. Compute it by hand once and the software output stops looking like magic: take everyone still at risk, count the events, multiply the running probability by one minus events divided by at risk.
| Time (months) | Events (d) | At risk (n) | 1 minus d/n | S(t) |
|---|---|---|---|---|
| 2 | 1 | 10 | 0.900 | 0.900 |
| 3 | 1 | 9 | 0.889 | 0.800 |
| 4 | 1 | 8 | 0.875 | 0.700 |
| 5 | 1 | 7 | 0.857 | 0.600 |
| 6 | 1 | 6 | 0.833 | 0.500 |
| 7 | 1 | 5 | 0.800 | 0.400 |
| 8 | 1 | 4 | 0.750 | 0.300 |
The denominator falls by one at each event time because nobody is censored before month 10 in this dataset. The three censored participants stay in the risk set until their censoring time, then leave without an event. That is why a participant who drops out at month 12 still helps you estimate survival through month 10.
In SPSS, go to Analyze, then Survival, then Kaplan-Meier. Put the time variable in Time and the status variable in Event, then choose your grouping variable under Compare Factor. Tick Log-rank in the Options box to get the group test from the same dialog. The Output Viewer gives you a Case Processing Summary panel first, then the survival table, then the curve with confidence bands.
library(survival)
fit <- survfit(Surv(Time, Status) ~ 1, data = mydata)
summary(fit)
plot(fit, xlab = "Months", ylab = "Survival probability")
median(fit$time[fit$surv <= 0.5])
The survival table has the same columns as the table you just calculated: time, number at risk, number of events, and estimated survival. Read it one row at a time and check the number at risk at your final event time. When it drops to a single digit, the tail of the curve is unstable, and most reviewers will not accept a median survival time read off it.
Median survival is the point where the curve crosses 0.5. Here it is 6 months. At month 12 the estimated survival is 0.30, because the curve has not moved since month 8. When the curve never crosses 0.5, the median is not reached, and saying so plainly beats quoting a number the data cannot support.
How to Compare Survival Between Groups
Use the log-rank test, also called the Mantel-Cox test, to compare two or more survival curves. It pools the risk sets across groups and compares observed with expected event counts, so unequal group sizes and unequal dropout do not distort it the way a chi-square test at one time point would.
In SPSS the result appears automatically once you set a compare factor, in a panel titled Comparisons (Gehan) or Comparisons of Groups showing the chi-square statistic, degrees of freedom, and p-value. In R the equivalent is survdiff:
fit <- survfit(Surv(Time, Status) ~ Group, data = mydata)
plot(fit)
survdiff(Surv(Time, Status) ~ Group, data = mydata)
The test answers one question: is the separation between these curves larger than chance usually produces. It says nothing about size or direction. So report it in two halves. Give the statistical result, then describe what the curves show: which group dropped earlier, and how far apart they sit through the middle of the follow-up period.
A significant p-value with two nearly identical curves shows up when you have very few events. A non-significant result with visibly diverging curves shows up when the sample is small. The curve is the honest picture; the p-value is a summary of it.
How to Run a Cox Regression in SPSS and R
Cox proportional hazards regression answers what the log-rank test cannot: does the difference persist once you adjust for other variables. It models the hazard at each moment in time, so it uses the whole follow-up rather than collapsing to one endpoint. It is semi-parametric, which means the baseline hazard is left unspecified and estimated from the data.
In SPSS, go to Analyze, then Survival, then Cox Regression. Put the time variable in Time and the status variable in Event, then place predictors in the Covariates box. There is no dependent variable field, and that trips up most beginners. The outcome is time and status together, which is why the dialog looks unlike every other regression window in the program.
fit <- coxph(Surv(Time, Status) ~ Group + Age, data = mydata)
summary(fit)
cox.zph(fit)
plot(fit)
The column that matters is exp(coef), the hazard ratio. An HR of 0.50 for Group B against Group A means participants in B had half the instantaneous risk of the event at any given moment, among those still at risk. Always read it against the reference category, which is the first level listed in your model formula.
Interpret the confidence interval before the point estimate. An HR of 0.50 with a 95% interval from 0.20 to 1.25 crosses 1, so the data are compatible with no difference at all. An HR of 0.50 with an interval from 0.35 to 0.72 stays below 1, and you can state the reduction with confidence. The interval describes precision, not size of effect.
A hazard ratio is not a risk ratio and it is not a change in median survival time. Readers mix these up constantly. Someone with an HR of 0.50 can still have a similar median time if the baseline hazard has a different shape, which is one reason survival curves stay in the results section next to the model.
Check proportional hazards before trusting any of it. The cox.zph function in R tests scaled Schoenfeld residuals, where the null hypothesis is that the hazard ratio is constant over time. SPSS offers the same idea through a log-minus-log plot in the Cox Regression dialog; curves running roughly parallel support the assumption, visibly crossing curves do not. Researchers report repeatedly that this check is skipped in practice, which is a shame when it takes two minutes.
If the assumption fails, stratify the offending variable in SPSS, or model it as a time-dependent covariate where its value changes over follow-up. Both are supported, and both beat quietly ignoring a violated assumption. A parametric Weibull or accelerated failure time model is a reasonable third option when you are willing to commit to a distribution shape.
Common Mistakes
Coding censoring backwards is the most frequent error and no program warns you. The symptom is a survival curve that rises toward 1 instead of falling. Fix: recheck which value your software treats as the event, in the dialog or the function argument.
Dropping censored cases is the second most common. It shortens follow-up and shrinks estimated survival probabilities, often substantially. Fix: keep those rows in the dataset with status set to the censored value.
Reading a median survival time off an unstable tail is the third. When the final row of the table shows one or two people at risk, the curve beyond that point is mostly noise. Fix: report the median only when it falls before the risk set thins out.
Skipping the proportional hazards check happens because the assumption gets taught rather than demonstrated. Fix: run cox.zph in R, or add a log-minus-log plot in SPSS, and write down what you saw.
Over-reading a hazard ratio as a survival percentage is another. An HR of 0.50 does not mean half the people are cured, and it does not mean 50 percentage points more survive.
Reporting a p-value with no curve leaves the reader nothing to look at. Always pair the log-rank result with a sentence describing the actual separation between curves.
Two design errors cause trouble before analysis even starts. Immortal time bias happens when you define a group using a period that required surviving, which manufactures protection out of the follow-up itself. And a chi-square test at a single time point discards most of your data; asking for the proportion event-free at 12 months is legitimate, but it is a different question from the one survival analysis answers.
Frequently Asked Questions
What is the Kaplan-Meier method used for in survival analysis?
The Kaplan-Meier method estimates the probability that a participant survives past each point in time, using every record you have instead of only the cases with events. It handles right censoring naturally, produces a step-function survival curve with confidence bands, and gives you a median survival time when the curve crosses 0.5. It is non-parametric, so it assumes no particular distribution of survival times.
How do I interpret the 95% confidence interval of a hazard ratio?
The interval shows the range of hazard ratios your data are compatible with. If it crosses 1, a null effect is still plausible and you cannot claim a difference at the 5% level. If the whole interval sits below 1, the protective effect is supported. Report the estimate and the interval together, and remember the interval describes precision rather than the size of the effect.
What is right censoring, and why does it matter?
Right censoring means the event was never observed for that participant because observation ended first, for example at study closure, loss to follow-up, or death from another cause. It matters because those participants still contribute information up to the moment they left. Deleting them, or worse, coding them as events, biases survival estimates and usually shrinks them noticeably.
When should I use Cox regression instead of the log-rank test?
Use the log-rank test when you only want to know whether two curves differ. Move to Cox regression when you need to adjust for covariates such as age, sex, or disease severity, when you want a per-variable effect estimate as a hazard ratio with a confidence interval, or when you have more than a couple of predictors. With one binary grouping variable and nothing to adjust for, the log-rank test is enough.
Why use survival analysis instead of a chi-square test?
A chi-square test on one time point throws away most of your information, because it only compares event counts at a single moment and ignores how long people were followed. Survival analysis uses every participant’s follow-up time, handles dropout properly, and lets you report a curve rather than one snapshot. It also gives you more power from the same sample size.
How do you check the proportional hazards assumption?
In R, run cox.zph on your fitted coxph model and inspect the residual plots; a flat trend with p above 0.05 supports the assumption. In SPSS, request a log-minus-log plot from the Cox Regression dialog and look for roughly parallel curves across levels of the covariate. If the assumption clearly fails, stratify that variable or model it as time-dependent rather than ignoring it.
Conclusion
Three things first, in order. Confirm what counts as the event, and that your status variable codes it the way the software expects. Compute the Kaplan-Meier estimate by hand for a handful of rows until the survival table stops looking like magic. Then compare groups with the log-rank test and describe the curve in words, not just a p-value.
Reach for Cox regression only when the question needs covariate adjustment, and check the proportional hazards assumption before you interpret any hazard ratio. If the curve does not look the way you expected, suspect the coding or the event definition before you suspect the statistics.