If you want to know how to run a Spearman correlation and when to use it, the short version is this: rank both variables, then correlate the ranks. Spearman’s rank correlation, reported as rho (rs), measures how strongly two variables move together in a steady, upward-or-downward way, and it runs from -1 to +1. Use it when your data are ordinal, skewed, full of outliers, or related in a monotone but not straight-line pattern. The whole procedure takes about five minutes in SPSS, R, or Stata. I have refreshed this walkthrough for 2026 so the menu paths and output labels match what students see today.
One thing to clear up before you start. Plenty of students have heard that Spearman is “for ordinal data only” and assume it is illegal on a scale or ratio variable. That is wrong. Spearman is a nonparametric coefficient, so it works on interval and ratio data perfectly well; ranking the values just discards some of the information those scales carry. Many people running these comparisons in R and SPSS are told the opposite. If you are unsure, and the data are roughly normal with no extreme outliers, run Pearson as well and report both.
Table of Contents
- 1What You Need
- 2Step-by-Step
- 3Step 1: Check the variables and data
- 4Step 2: Run the analysis in SPSS
- 5Step 3: Run the analysis in R
- 6Step 4: Run the analysis in Stata
- 7Step 5: Interpret the result
- 8Step 6: Report the result
- 9Error checks at each step, with the fix
- 10Common Mistakes
- 11Frequently Asked Questions
- 12When should I use Spearman correlation instead of Pearson correlation?
- 13Does Spearman correlation require normally distributed data?
- 14How do I interpret a positive or negative Spearman’s rho?
- 15What should I do if my data contain many tied ranks?
- 16Can a significant Spearman correlation prove that one variable causes the other?
- 17How do I report a Spearman correlation in APA style?
- 18Conclusion
What You Need
You need very little. Two variables measured on the same cases, a way to hold your data in rows, and one piece of statistics software. That can be SPSS, R, Stata, Jamovi, or even Excel. The hardest part is not the software; it is deciding honestly whether your data meet the conditions.
Before you calculate anything, check five things.
- Two variables. Spearman needs exactly two at a time. With more, you run it repeatedly and correct for multiple comparisons.
- Paired cases. Each row must be the same person, object, or observation on both variables. Rank the rows as matched pairs, not as two separate lists.
- A measurement level that preserves order. Ordinal, interval, or ratio all qualify. Nominal data with no inherent order do not, because there is nothing to rank.
- Missing values handled deliberately. SPSS drops cases pairwise by default, which means the two coefficients in a correlation matrix can rest on different sample sizes.
- A check for ties. Tied ranks are common in survey data. They change the coefficient slightly and the p-value considerably.
Define monotonic relationship carefully, because it is the term most often misused. It means that as one variable increases, the other consistently increases or consistently decreases, with no reversals in direction. The shape can curve, plateau, or bend sharply. A straight line is not required, which is exactly why Pearson can miss a relationship that Spearman finds.
Step-by-Step
Step 1: Check the variables and data
Open your data and look at the two variables before you touch a menu. Check the measurement level in the variable view, then scan for missing codes, impossible values, and blanks that were entered as zero or 999. Those get read as real numbers and quietly wreck a coefficient.
Next, plot the two variables. A scatterplot tells you in two seconds whether the relationship is straight-line or curving, and whether any point sits far away from the rest. If the cloud is a clean line with no odd points, Pearson’s r is probably the better report and Spearman is optional.
Look at how many values repeat. A five-point Likert item with 60 respondents will have ties no matter what. Count how many distinct values share the largest rank block; if more than half the observations fall into a single tie group, the ranks are carrying very little information and Kendall’s tau-b is usually the better call.
Step 2: Run the analysis in SPSS
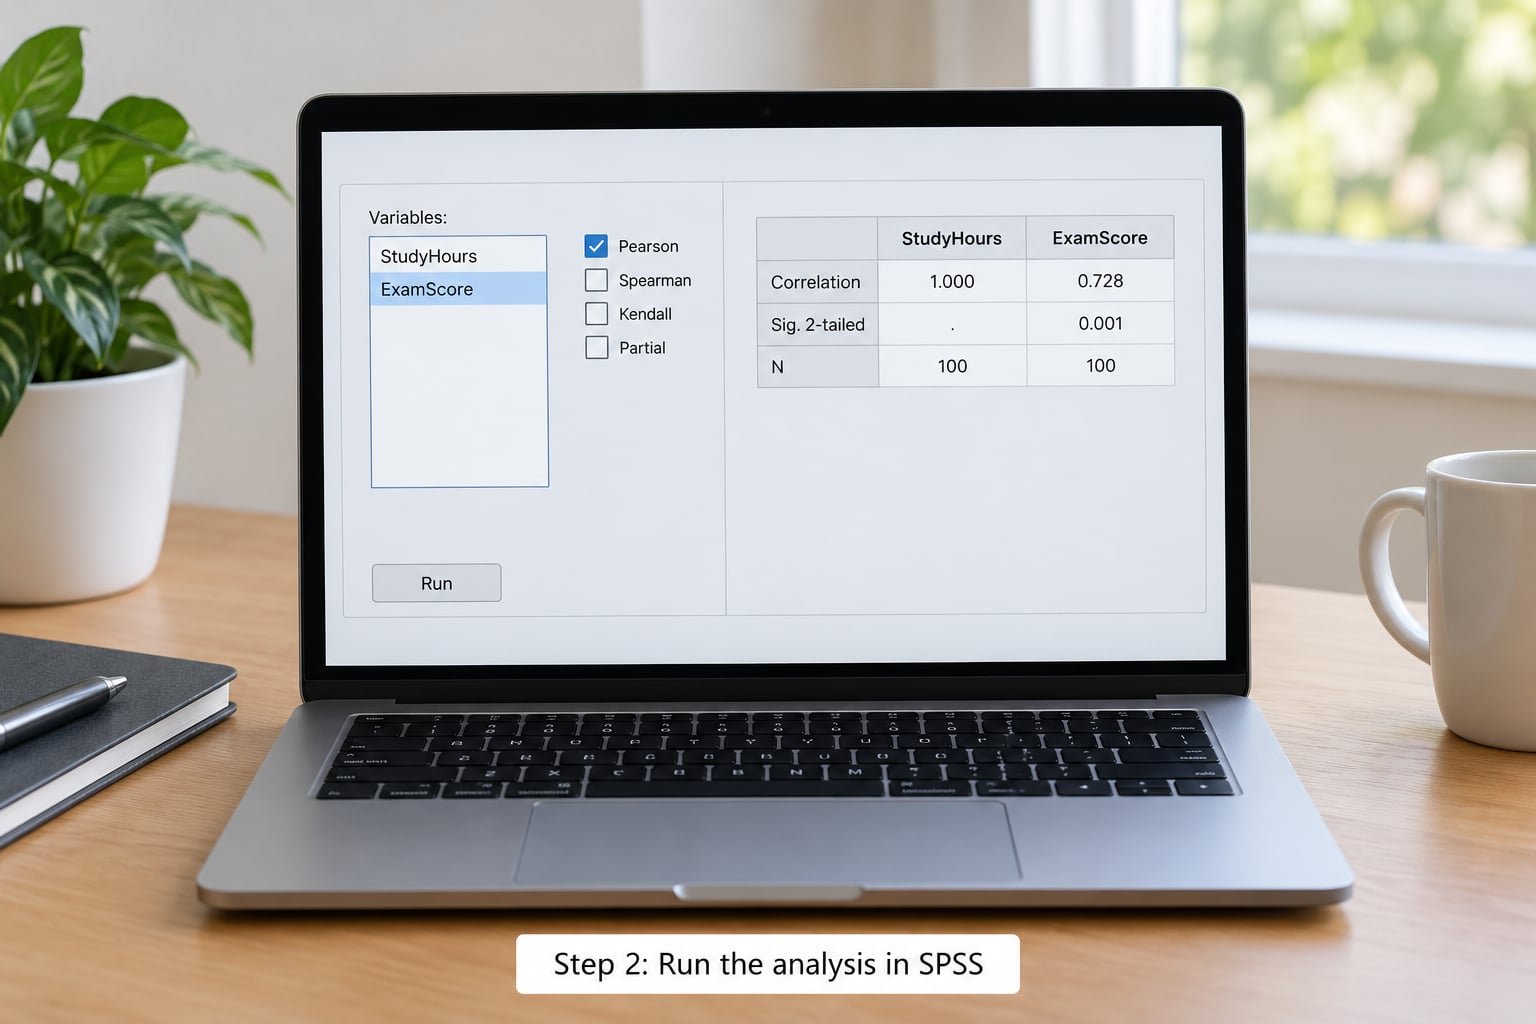
Open the Data Editor, click the Variable View tab, and confirm both variables are coded as Ordinal or Scale. SPSS treats ordinal variables correctly by default, but check the Measure column anyway.
Then walk the menu path.
- Click Analyze on the menu bar.
- Choose Correlate, then Bivariate.
- In the Variables box, click your first variable, then hold Ctrl and click the second. Click the arrow to move both across.
- Tick Spearman under Correlation Coefficients. Leave Pearson unticked if you want a clean Spearman output.
- Under Significance Level, choose Two-tailed (the default). Leave the significance level at 0.05 unless your field uses another threshold.
- Leave Missing Values on Pairwise deletion if you want maximum data retained, or switch to Listwise when you need one consistent N across the whole matrix.
- Click OK. The output window opens with the Correlations table.
The result is a symmetric table, so the same number appears twice, mirrored across the diagonal. Three columns matter.
| Column | What it is | How to read it |
|---|---|---|
| Correlation Coefficient | Your rho value, from -1 to +1 | Sign gives direction, size gives strength |
| Sig. (2-tailed) | The p-value for a two-sided test of no association | Below your threshold means the association is unlikely to be chance |
| N | Number of complete paired cases used | Check it against your expected sample size |
Two labels in the output trip people up. The note “Correlation Coefficients: measured at ordinal level” is informational, not a warning. And the small box of significant correlations is SPSS repeating which pairs cleared your threshold; you do not need to report it separately from the table.
On the significance level box: changing it from 0.05 to 0.01 does not change rho. It only changes which stars SPSS prints and the wording of the note beneath the table.
Step 3: Run the analysis in R
R needs no package for this. cor.test() ships with base R and handles the two-variable Spearman test directly.
cor.test(study_hours, exam_score, method = "spearman")The output gives you the sample estimate of rho under S, the p-value, and a confidence interval. Because R computes an exact p-value only when there are no ties, you may see this line:
Warning: Cannot compute exact p-value with tiesThat message is informational, not a failure. R falls back to the normal approximation, which is accurate for decent sample sizes and shaky below roughly 20 cases. If you have ties and a small sample, set exact = NULL to force the approximation deliberately rather than by accident, and say so in your write-up.
For a quick rank check before testing, cor(x, y, method = "spearman") returns just the coefficient.
Step 4: Run the analysis in Stata
Stata’s built-in spearman command takes two variables and prints the coefficient, the p-value, and the observation count.
spearman study_hours exam_scoreThe output lists the Spearman correlation as rho, then Prob > chi2 for the significance level, and finally the number of observations. Stata drops observations with missing values in either variable and tells you how many it used.
For a matrix of many pairwise coefficients, pwcorr study_hours exam_score attendance, sig prints them with significance stars and stars adjusted for the number of comparisons.
Step 5: Interpret the result
Start with direction. A positive rho means the variables rank in the same order: whoever is high on one is high on the other. A negative rho means the opposite, whoever is high on one is low on the other. A rho of zero means no steady association at all, which is not the same as “no relationship”; a perfect U-shape scores near zero.
Then look at strength. These are conventional labels, and they are guidelines rather than thresholds.
| Absolute value of rho | Strength | What it usually means in practice |
|---|---|---|
| 0.00 to 0.19 | Very weak or negligible | The ranking carries almost no usable signal |
| 0.20 to 0.39 | Weak | Real but rarely useful on its own for prediction |
| 0.40 to 0.59 | Moderate | Worth reporting; rarely worth acting on alone |
| 0.60 to 0.79 | Strong | Stable ordering across most of the sample |
| 0.80 to 1.00 | Very strong | The two rankings are nearly interchangeable |
Next, check significance against the p-value, and hold it against the effect size. A p-value below .05 tells you an association is unlikely to be pure chance in a sample this size. It does not tell you the association is large. With a big enough sample, a rho of 0.08 will clear significance, and a p-value of 0.03 says nothing about magnitude. Report both numbers, always.
Sample size is where students get caught out. A moderate rho can fail to reach significance in a small sample. With 8 pairs you need roughly rho of 0.74 for a two-tailed p below .05; with 30 pairs the bar drops to about 0.36; with 100 pairs, about 0.20. A non-significant result from 12 participants is a statement about power, not about the relationship.
Finally, keep the meaning narrow. Rho describes monotonic association. It cannot establish that one variable causes the other, no matter how large or how significant it is.
A worked example makes this concrete. Suppose eight students recorded study hours and exam score:
| Student | Study hours (X) | Exam score (Y) | Rank X | Rank Y | d | d squared |
|---|---|---|---|---|---|---|
| 1 | 2 | 71 | 1 | 5 | -4 | 16 |
| 2 | 3 | 60 | 2 | 2 | 0 | 0 |
| 3 | 4 | 64 | 3 | 3 | 0 | 0 |
| 4 | 5 | 68 | 4 | 4 | 0 | 0 |
| 5 | 6 | 55 | 5 | 1 | 4 | 16 |
| 6 | 7 | 74 | 6 | 6 | 0 | 0 |
| 7 | 8 | 79 | 7 | 7 | 0 | 0 |
| 8 | 9 | 85 | 8 | 8 | 0 | 0 |
Student 5 studied plenty and still scored lowest. That single reversal drives everything. Sum of squared differences is 32, so rho = 1 – (6 x 32) / (8 x (8 squared – 1)) = 1 – 192/504 = 0.62. That is a strong, positive association by the labels above, yet with only eight pairs it is not statistically significant: rho would need to reach about 0.74 to clear .05, giving a p-value of roughly .10. Notice that Pearson’s r on this same dataset also lands at about 0.62, because the reversal is symmetric. Had student 5 scored 5 rather than 55, Pearson would collapse while rho stayed near 0.5.
Step 6: Report the result
Write the variables, the coefficient, the p-value, and the sample size in one sentence. Give the variable names in plain words rather than variable codes where the reader can follow it.
A template you can copy:
A Spearman’s rank correlation showed that [variable 1] was [moderately/strongly/weakly] associated with [variable 2], rs(degree of freedom) = [value], p = [value], N = [number], where the [sign] indicates that [brief practical interpretation].
A filled-in example:
A Spearman’s rank correlation indicated a moderate positive association between study hours and exam score, rs(6) = 0.62, p = .10, N = 8. The positive sign indicates that students who studied more hours tended to score higher.
Reporting the degrees of freedom as n minus 2 follows the usual convention for a correlation test. If you ran one of the software options that reports an exact p-value or a bootstrap interval instead, say which one you used. Also state how you handled missing values, because pairwise deletion changes your N silently.
Do not report rho squared as a percentage of variance explained. That shortcut belongs to linear models with an intercept, and applying it to ranks overstates how much the variables have in common.
Error checks at each step, with the fix
These are the errors I see most often in student analyses, each with the fix that resolves it.
| What went wrong | Warning sign | Fix |
|---|---|---|
| Treating an ordinal score as if the gaps between levels were equal | Reporting a mean for a single five-point rating as though it were a precise measurement | Run Spearman rather than Pearson, and describe the response distribution with counts or a median, not a mean |
| Running Pearson on data with extreme outliers | A scatterplot where one point sits far from the cloud, or a skewness value well past plus or minus 2 | Switch to Spearman, or transform the variable before running Pearson |
| Ignoring ties | R prints the exact p-value warning, or SPSS reports many identical values in a Likert column | Report the tie count, expect the approximation-based p-value, and consider Kendall’s tau-b |
| Overstating the result | The word “caused”, “causes”, or “led to” appears in the interpretation | Say “associated with” or “related to” and describe the design that would be needed for a causal claim |
| Failing to report missing-value handling | The N in the output is smaller than your sample and is not explained | State whether you used listwise or pairwise deletion and give the N you analysed |
| Reading significance as importance | A p-value of 0.001 reported without the coefficient alongside it | Put rho first, then p, then your own sense of practical value |
| Running many pairs and reporting them all as significant | A long bivariate matrix with no adjustment | Apply a multiple-comparison correction such as Bonferroni, or pre-specify the pairs you care about |
Choosing between the three common correlation coefficients comes down to your data shape.
| Feature | Spearman’s rho | Pearson’s r | Kendall’s tau-b |
|---|---|---|---|
| Works on | Ordinal, interval, ratio | Interval, ratio | Ordinal, interval, ratio |
| Needs normality | No | Yes, approximately | No |
| Affected by outliers | Very little | Substantially | Very little |
| Detects | Monotonic relationships | Linear relationships only | Monotonic relationships |
| Handles ties | Approximation needed | Not applicable | Built in via the tau-b correction |
| Best for | Ranked survey items, skewed data, general reporting | Clean interval data with a straight-line fit | Very small samples or heavy ties |
For very small datasets, under 20 paired observations, Kendall’s tau-b often gives a more trustworthy p-value because it handles ties explicitly. The trade is interpretation: tau values run lower than rho for the same data, so results are harder to explain to a general audience.
Common Mistakes
Before you submit, four quick checks catch most of the problems above.
- Plot your data. If the points fall on a clean straight line with no strays, report Pearson’s r, or both coefficients, and say why.
- Check the N in the output against your expected sample size. A mismatch means missing values were dropped.
- Confirm your variables are on scales that can be ranked. Nominal categories with no order have no meaningful rho.
- Read your own interpretation back and hunt for causal verbs. Replace them with association language.
One limitation deserves its own mention. Spearman only captures monotonic association, so a strong curved or U-shaped relationship can score near zero. If your scatterplot shows a curve, fit the relationship as a curve rather than reaching for a rank correlation that will report zero.
Frequently Asked Questions
When should I use Spearman correlation instead of Pearson correlation?
Use Spearman when your data are ordinal, when either variable is strongly skewed, when outliers could distort a linear coefficient, or when the relationship rises and falls consistently without being straight. If the data are roughly normal, the relationship is close to linear, and no point dominates, Pearson’s r is the better primary report. Running both and comparing them is a reasonable habit in exploratory work, since a large gap between the two values is itself a finding worth reporting.
Does Spearman correlation require normally distributed data?
No. That is one of its main advantages. Spearman converts the values to ranks before correlating them, so it makes no assumption about the shape of the underlying distribution. You can use it confidently with skewed variables, small samples, and data that contain influential outliers. The normality requirement belongs to Pearson’s r, not to Spearman’s rho.
How do I interpret a positive or negative Spearman’s rho?
The sign gives direction and the size gives strength. A positive rho means the two variables rank in the same order, so high values on one pair with high values on the other. A negative rho means the reverse. A rho near zero means there is no steady upward or downward association, which is not the same as no relationship at all, since a strong U-shape also scores near zero. The full coefficient runs from -1 to +1.
What should I do if my data contain many tied ranks?
First, count how many values share the same rank. In R, tied data trigger the message Cannot compute exact p-value with ties, and the software switches to a normal approximation that becomes unreliable below roughly 20 observations. Ties shrink rho slightly and widen the p-value. If more than half of your cases fall into one tie group, the ranks carry little information and Kendall’s tau-b is a better choice because it corrects for ties directly. Report which method produced your p-value.
Can a significant Spearman correlation prove that one variable causes the other?
No. Spearman measures monotonic association only, so it can describe how two variables rank together but cannot establish direction of influence or rule out confounding. A small p-value shows the association is unlikely to be chance; it says nothing about causation. Making a causal claim requires a study design that controls for alternative explanations, such as random assignment, a longitudinal design, or a credible natural experiment.
How do I report a Spearman correlation in APA style?
Give the coefficient, the degrees of freedom, the p-value, and the sample size in one sentence. A typical line reads: A Spearman’s rank correlation indicated a moderate positive association between study hours and exam score, rs(6) = 0.62, p = .10, N = 8. Use the symbol rs in text and italicise it, omit the p-value when it is not significant unless your style guide requires it, and never present the result without describing the variables and the direction of the association.
Conclusion
Start by plotting your two variables and looking at their shapes. That single step tells you whether you need Spearman at all, and it catches the missing values and outliers that quietly damage a coefficient. If the ordering is clear but the line is not, run Spearman through Analyze, Correlate, Bivariate in SPSS, or with cor.test(x, y, method = "spearman") in R, then read the direction, the magnitude, and the p-value together rather than separately. Report rho with your N and your missing-value handling, describe the association as an association, and leave causal claims to designs built for them.