Decide how many factors to retain by treating the choice as evidence, not arithmetic. Run parallel analysis first, compare its answer with the scree plot, percent variance explained and communalities, then keep the smallest number of factors that are stable, show simple structure, and match what you actually want to measure.
The honest version takes maybe 45 minutes of work in SPSS, R, JASP or jamovi. Most of the confusion I see comes from treating one rule as the rule, when the rules disagree by design and the disagreement is the useful part.
In exploratory factor analysis, a factor is a latent construct that is inferred from the pattern of correlations among observed items. Retaining a factor means deciding that this pattern is strong enough and distinct enough to count as a separate dimension rather than measurement noise.
Table of Contents
- 1What You Need
- 2Step-by-Step: How to Decide How Many Factors to Retain
- 31. Establish the Conditions for EFA
- 42. Check Correlations and Matrix Adequacy
- 53. Generate a Range of Candidate Solutions
- 64. Run and Interpret Parallel Analysis
- 75. Compare the Candidate Factor Solutions
- 86. Test Whether the Chosen Solution Holds Up
- 97. Document the Retention Decision
- 10Common Mistakes
- 11Frequently Asked Questions
- 12What does it mean to retain a factor in exploratory factor analysis?
- 13Is Kaiser’s criterion enough to decide how many factors to retain?
- 14What does a clear break in the scree plot mean?
- 15Should every factor contain at least three indicator variables?
- 16When should I use confirmatory factor analysis instead of EFA?
- 17Conclusion
What You Need
Before any retention rule produces a number, four conditions have to hold. If they do not, the count is meaningless no matter how sophisticated the criterion is.
A usable correlation matrix. Factor analysis works on correlations, so you need enough interrelated variables with no missing-data holes left unfilled. Impute or drop cases before you start, not after.
A sample that can support the structure. The usual conventions scale with how many indicators each factor carries and how strongly they load. These are starting points for planning, not guarantees.
A correlation matrix that is factorable. You will check this with the KMO statistic, Bartlett’s test of sphericity and the anti-image matrix in step 2.
Software that will run parallel analysis. SPSS, R, JASP and jamovi all can, and the procedures are named below.
An agreed purpose for the factors. Are you reducing 40 items into a handful of composite scales, or testing whether a theory’s dimensions appear in the data? The purpose changes which criterion you let lead, and you should write it down before you look at any output.
| Indicators per factor | High communalities (loading around .70) | Moderate communalities (loading around .45) |
|---|---|---|
| 3 | around 150 | around 250 |
| 4 | around 200 | around 300 |
| 5 | around 250 | around 350 |
| 10 | around 500 | around 600 |
These come from the widely cited 5-to-10-observations-per-variable convention extended for indicator count per factor. Parallel analysis is more tolerant of smaller samples than the Kaiser criterion, because it estimates sampling error empirically rather than assuming a fixed benchmark.
Step-by-Step: How to Decide How Many Factors to Retain
No single criterion determines the final solution, so the process works by generating competing estimates and then weighing them against each other. Seven steps, in this order.
1. Establish the Conditions for EFA
Begin by pinning down the measurement purpose, because it decides which criteria you treat as decisive. Item reduction for a scale and dimension discovery for a theory place different demands on the solution, and the same data can defensibly support two different counts depending on which you are doing.
Then check the assumptions that the retention rules quietly depend on.
Variables. EFA is for interval or ratio variables that share a common unit of measurement. Mixing a Likert item with annual income produces a correlation matrix that has no single meaning.
Observations. Each case needs to be independent. If your participants are nested in schools, teams or clinics, ordinary EFA understates the standard errors and the parallel analysis envelope will be too generous.
Distribution. Serious univariate skew or strong outliers distort the correlations. Tabachnick and Fidell suggest checking skewness and kurtosis against roughly 2 and 7 as rough thresholds before proceeding.
Ordinal data. If your items are 5-point or 7-point Likert, treating them as continuous can either inflate or suppress eigenvalues and shift the retained count. A polychoric correlation matrix with diagonally weighted least squares estimation is the careful option when items are coarsely scaled or distributions are badly skewed.
Sample size. Use the table above as a floor, and check that your communalities are plausible before you trust any rule. Parallel analysis itself tells you something here: a random-data benchmark very close to the observed eigenvalues is a signal that the sample is too small for stable structure.
2. Check Correlations and Matrix Adequacy
Interpret no retention result until the correlation matrix passes inspection, because the failure modes here masquerade as factor solutions.
Look first at the pattern of correlations themselves. Very low correlations, say most below .30, mean the variables share too little variance for a stable common-factor solution. Very high correlations, say many above .85, point to overlapping indicators or a near-multicollinearity problem.
Then run the three standard checks.
KMO statistic. Values above .80 are usually taken as good, .60 to .80 as acceptable, and below .60 as poor. Below .60, factor the items in smaller blocks rather than reporting a single solution.
Bartlett’s test of sphericity. This tests the null that the correlation matrix is an identity matrix. A significant result is what you want. A non-significant result means the items are not interrelated enough to analyse, and no retention rule can rescue the data.
Anti-image matrix. The diagonal gives partial correlations and partial covariances. Negative values mean the matrix is not factorable in the way you hoped, and again, that is a stopping point rather than something to argue past.
For a clean worked check, the pattern to aim for is most correlations somewhere between .30 and .70, a KMO above .80, a significant Bartlett result, and no negative anti-image diagonal. Anything else means the retention decision comes later.
3. Generate a Range of Candidate Solutions
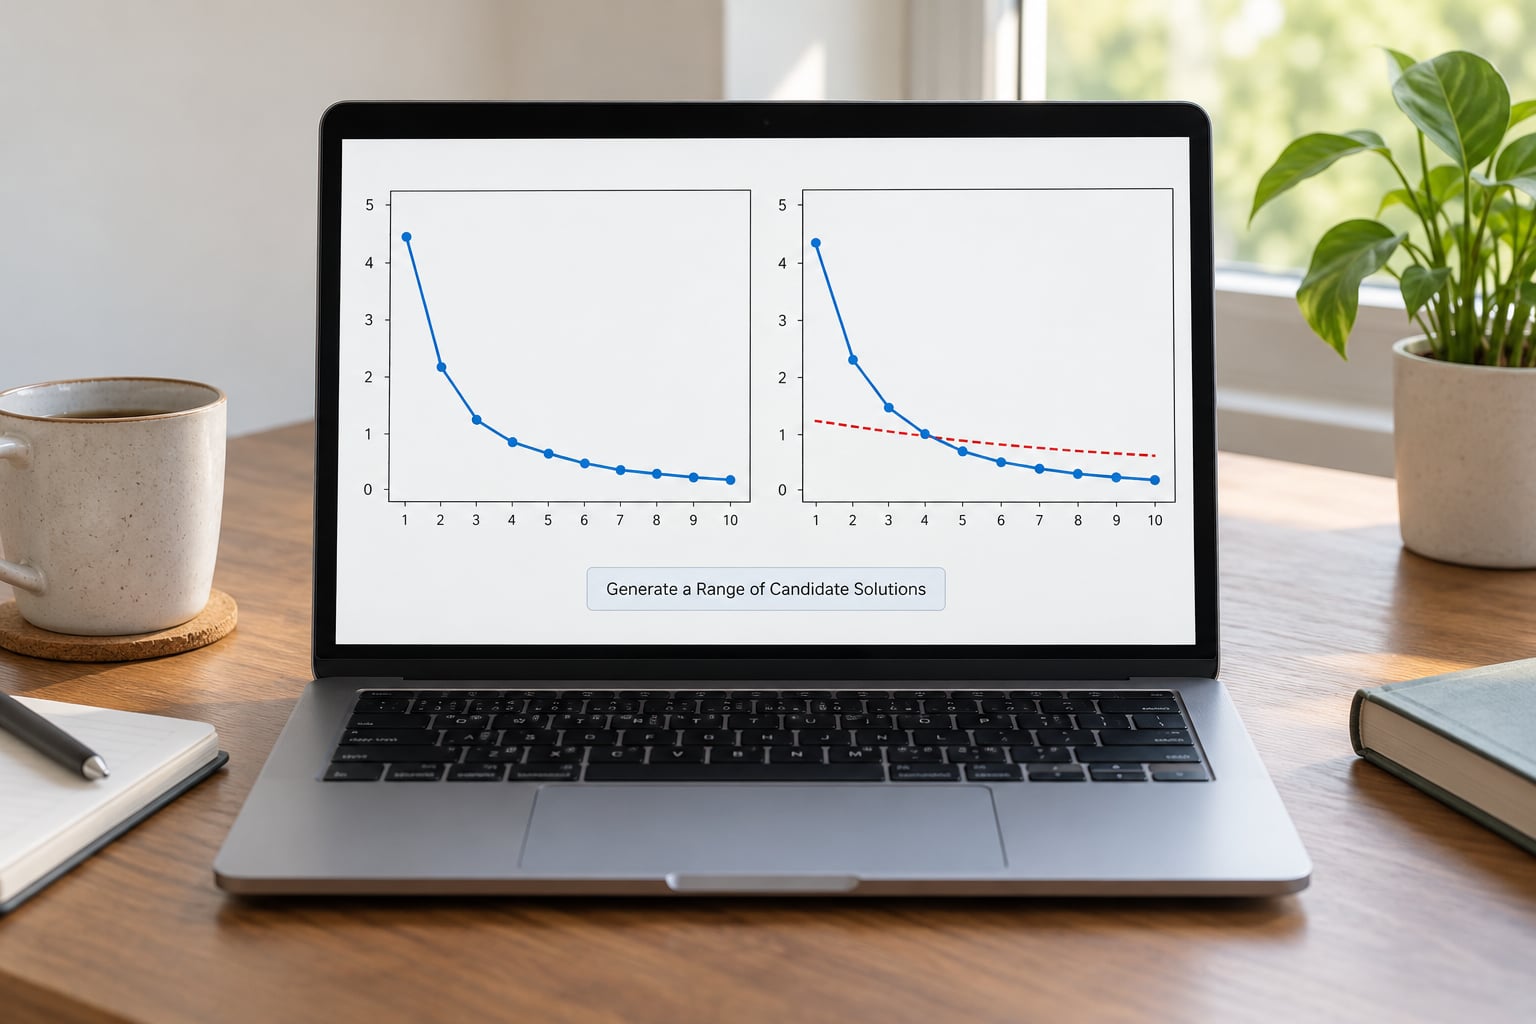
Each retention rule compares the observed structure against a different benchmark, so each gives a different answer. Treat the spread between them as your candidate range, not as an error to be resolved.
Eigenvalue greater than one (Kaiser, 1960). Retain every factor whose eigenvalue exceeds 1. The reasoning is that under pure noise each variable contributes an eigenvalue of about 1, so anything above that indicates shared variance. In practice this rule over-retains, and the reason is sampling error: eigenvalues in a random sample of real data do not stay near 1, they drift above it often enough that the criterion accumulates extra spurious factors.
Scree plot. Plot the eigenvalues in descending order and look for the point where the curve visibly flattens, the elbow or break. It is quick and it sees the gross shape of the data, but it is subjective and degrades badly when the plot has no clean break. When the elbow is ambiguous, read the plot in two directions: from the smallest eigenvalues on the left looking for the last elbow, and from the largest on the right looking for the first one. If those two readings differ, write down a bracket rather than picking one.
Percent variance explained. Decide an acceptable total first, commonly somewhere between 50 and 75 percent, then count how many factors reach it. This rule has a built-in upward bias, since each added factor explains more variance by definition, so it will always push you toward more factors.
Parallel analysis (Horn, 1965). Compare observed eigenvalues against eigenvalues generated from random data with the same number of variables and cases. See step 4.
Velicer’s MAP (1987) and VSS complexity. MAP retains the number of factors minimising the average squared partial correlation, which rewards parsimony by penalising the residual variance that extra factors leave behind. Very simple structure evaluates how close the solution comes to the ideal of each indicator loading on one factor only.
Communalities and average minimum loading. A solution that needs every item to load on two factors at .45 has not found structure, whatever its count. The minimum average loading criterion retains the largest number of factors for which the average of the lowest loadings per column still stays above .40. It often agrees with parallel analysis.
| Rule | Compares | Typical bias | Rely on it when |
|---|---|---|---|
| Kaiser eigenvalue > 1 | Eigenvalues against 1 | Over-retains, especially in smaller samples | You need a fast upper bound |
| Scree plot | Shape of the eigenvalue curve | Subjective; unreliable without a clear break | The plot shows an obvious elbow |
| Percent variance explained | Cumulative variance against a target | Under-retains a shared dimension that explains little variance | A minimum coverage target is required |
| Parallel analysis | Observed vs simulated random-data eigenvalues | Under-retains occasionally with ordinal or skewed data | Always, as your primary quantitative rule |
| Velicer’s MAP | Average squared partial correlation | Tends to under-retain slightly | As a second quantitative check |
| Average minimum loading | Lowest loading per column against .40 | Can under-retain complex constructs | You care about clean simple structure |
| Theory and interpretability | Your measurement purpose | Subject to motivated reasoning | Always, as the final veto |
4. Run and Interpret Parallel Analysis
Parallel analysis answers a different question from Kaiser. Instead of asking whether an eigenvalue exceeds a fixed value, it asks whether the eigenvalue exceeds what pure chance would produce for a dataset of this size. That is why it corrects the sampling-error problem rather than merely working around it.
The procedure is the same in every package.
Generate a set of random datasets, usually 100 or more, each with the same number of variables and the same number of cases as your real data. Retain only the correlation structure, not the factor structure.
Run the same factor extraction on each random dataset and save the eigenvalues from every run.
Take the 95th percentile of the simulated eigenvalues at each position. This is the benchmark, and the choice of percentile is what makes the criterion probabilistic rather than arbitrary.
Plot the observed and simulated eigenvalues on the same axes, then count the factors whose observed eigenvalues fall above the simulated line. That count is the parallel analysis answer.
In R, the psych package does all of this in one call. The function psych::fa.parallel takes your correlation matrix, the number of factors you want to compare across, and arguments for the simulation count and percentile. The nFactors package returns a single retention verdict from parallel analysis, MAP, VSS and several other criteria in one table. The factoextra package handles the plotting and the rotated loadings afterwards.
In SPSS, the built-in Factor Analysis dialog does not run parallel analysis, so you simulate it yourself. Run Analyze, then Regression, then Random Sample Generation, with the correlation matrix as input and your case count as the sample size, generate 100 or so random matrices, then extract factors from each one and read off the simulated eigenvalues. In JASP and jamovi, the Parallel Analysis module under Factor does the whole loop in the interface, which is why they are worth learning before you build the SPSS version by hand.
Read the result honestly. If parallel analysis returns 12 factors on a 30-item scale, that is information, not an instruction. It usually means the variables are densely intercorrelated, that the sample is small relative to the structure, or that there is more dimensionality than your measurement model assumed. Before trimming toward your preferred count, check the communalities and look at whether the extra factors are nameable.
5. Compare the Candidate Factor Solutions
Do not pick a count in the abstract. Extract and rotate the solutions inside your candidate range, typically K-1, K and K+1 around the parallel analysis result, then compare them side by side. Retention is decided before rotation, but the quality of a solution is only visible after it, which is why the two steps are separated rather than fused.
Fill in a table like this for each candidate.
- Retained factors. The count you are evaluating.
- Total percent variance explained. Higher is not automatically better; check it is not inflated by a factor that is just noise.
- Simple structure. Does each item load strongly on one factor and weakly on the rest, or is the pattern smeared across everything?
- Cross-loadings. Count items loading above .40 on two or more factors. More than about 20 to 25 percent of items with serious cross-loadings means the count is wrong.
- Communality estimates. Flag any communality above 1.00, a Heywood case, and any communality below .30, which usually means the item does not belong.
- Residual correlations. Large residuals between items that should be unrelated indicate the solution is under-retained. Zuo and Richman’s chi-square test of residual correlations formalises this.
- Interpretability. Can you name every factor and say what it measures? A factor you cannot name is not a finding.
If the K-1 solution shows fewer serious cross-loadings and no nameable factor disappears, it is probably the right answer. If K+1 splits a genuine dimension into two halves that each name cleanly and have at least three loadings, K+1 may be correct.
6. Test Whether the Chosen Solution Holds Up
A defensible factor count is stable, not lucky. Run the neighbouring solutions with a second extraction method, such as principal axis factoring if you used principal components, and with a second rotation, such as oblimin if you used varimax. The count should not change.
Then run cross-validation. Split the sample in half randomly and repeat the analysis on each half. If you get four factors in both halves with a similar loading pattern, the structure is probably real. If you get three in one and six in the other, the count was not identified by the data and you should treat the current result as provisional.
Where a confirmatory model is available, comparing K against K-1 and K+1 using fit indices adds a further check. This is not a replacement for EFA, since you need a model to fit, but for a scale with published dimensionality it is a reasonable way to test neighbouring solutions.
State plainly in your write-up that EFA results are sample-dependent. A factor structure is a finding about your data, not a fixed property of the instrument, and a different sample may support a different count.
7. Document the Retention Decision
The retained count is the first decision an examiner asks about, so report it explicitly. A methods paragraph covering the following will usually satisfy the question.
State the data screening results (KMO, Bartlett, any items removed), then each criterion you applied and what it returned, for example that the Kaiser criterion retained six factors while parallel analysis and Velicer’s MAP retained four. Give the final count and the reason: it was the smallest solution showing simple structure, with no Heywood cases, at least three loadings above .45 per factor, and interpretable factors consistent with the study’s purpose. Name the extraction method, the rotation method, and whether you handled ordinal data with polychoric correlations and diagonally weighted least squares.
Finish with fit or residual statistics if you computed them, and note the retained percent variance. A reader should be able to reconstruct your reasoning without guessing, and if they do disagree with your count they will be disagreeing with the evidence rather than with you.
Common Mistakes
Choosing the count from the scree plot alone. It is the most subjective rule available, and it fails on exactly the datasets where you most need a clear answer. Use it as one input.
Treating Kaiser’s criterion as definitive. The default in most SPSS dialogs is eigenvalue greater than or equal to 1, which makes it look authoritative. It is a rough rule derived in 1960 and known to over-retain.
Running EFA on inadequately related variables. A poor KMO or non-significant Bartlett result will produce a solution no retention rule can rescue. Fix the correlation matrix first.
Choosing the parsimonious solution before checking communalities. Dropping from eight factors to three because it looks tidier can leave you with two poorly measured factors and a large residual correlation matrix. Check the loadings before you reward parsimony.
Over-rotating. If factors correlate above about .80 in the rotated solution, the rotation has pushed a single dimension into two thin ones, and the retained count has drifted upward as a result.
Reporting a fixed count as if it were sample-invariant. If a split-half check disagrees with the full-sample result, report the disagreement rather than the tidier number.
One habit worth building in: run the retention rules first, write down all the numbers before rotating anything, and compare them afterwards. Deciding the count while staring at a loading table is how motivated reasoning creeps in.
Frequently Asked Questions
What does it mean to retain a factor in exploratory factor analysis?
Retaining a factor means keeping it as a real dimension in the solution rather than treating its variance as noise. Each retained factor should explain enough shared variance to matter, load strongly on at least three indicators, and correspond to something you can name and interpret. Retaining too many leaves thin factors that are hard to label, while retaining too few forces unrelated indicators together and leaves large residual correlations.
Is Kaiser’s criterion enough to decide how many factors to retain?
No. Kaiser’s criterion retains every factor with an eigenvalue above 1, and it tends to over-retain, particularly in smaller samples, because eigenvalues in a random sample drift above 1 more often than the rule assumes. It is a useful upper bound and a quick sanity check. Most researchers use it alongside parallel analysis and interpretability rather than on its own, and report what each rule returned.
What does a clear break in the scree plot mean?
A break or elbow is the point where the steep drop in eigenvalues levels off into a flatter tail, which usually signals the end of the genuine common-factor structure. A clear break makes the retained count fairly obvious. When the curve tapers gradually with no obvious elbow, the scree plot cannot arbitrate the count, and you should rely on parallel analysis, communalities and interpretability instead.
Should every factor contain at least three indicator variables?
Most guidance says yes, because a factor with one or two loadings cannot be cleanly separated from those items and is usually a sign the count is too high. This matters most when factors are orthogonal. With oblique rotation, correlated factors can be stable with two indicators each, but the solution is harder to defend, so treating three indicators as the floor is the safer default.
When should I use confirmatory factor analysis instead of EFA?
Use confirmatory factor analysis once you have a specific model to test, usually a published scale with an established factor structure, and you want to know whether that structure holds in your sample. EFA is data-driven and asks how many factors are present. CFA is theory-driven and tests a model you already committed to, reporting chi-square, comparative and root mean square error fit indices.
Conclusion
Screen the data first so you know the matrix can support a factor solution, run parallel analysis to get a strong candidate count, and write down what Kaiser, the scree plot and percent variance explained say alongside it. Then extract and rotate the neighbouring solutions, and keep the smallest number of factors that show simple structure, no Heywood cases, at least three solid loadings each, and a meaning that matches what your study set out to measure.
That reasoning, written out in your methods section, is the answer to how to decide how many factors to retain. Any single rule on its own will get challenged eventually.