A composite score is one number built from several survey items that are meant to measure the same thing. You build it by coding every item so it points the same direction, checking that the items hang together, and then applying a single arithmetic rule — usually a sum or a mean — to each respondent’s row of answers. Knowing how to create composite scores from survey items takes about an hour once the data is clean.
The order matters more than the arithmetic. Reverse-coding and reliability checks have to happen before you combine anything, because a sum built from mis-keyed items produces a plausible-looking variable that measures nothing.
Below is the full chain: what you need, the eight steps, the mistakes that trip people up, and a reporting sentence you can paste into a paper.
Table of Contents
- 1What You Need
- 2How to Create Composite Scores from Survey Items
- 3Step-by-Step
- 4Step 1: Identify the Items That Belong Together
- 5Step 2: Check and Prepare the Survey Data
- 6Step 3: Choose the Scoring Method
- 7Step 4: Reverse-Code Items With Opposite Wording
- 8Step 5: Calculate the Composite Score
- 9Step 6: Standardize the Score When Comparing Scales
- 10Step 7: Check Reliability and Validity
- 11Step 8: Interpret and Report the Composite Score
- 12Common Mistakes
- 13Frequently Asked Questions
- 14How do I calculate a composite score in SPSS?
- 15What is a composite z score?
- 16How do I reverse score a Likert scale?
- 17How do I interpret a composite score?
- 18Is composite reliability the same as Cronbach’s alpha?
- 19Why is my Cronbach’s alpha low?
- 20Conclusion
What You Need
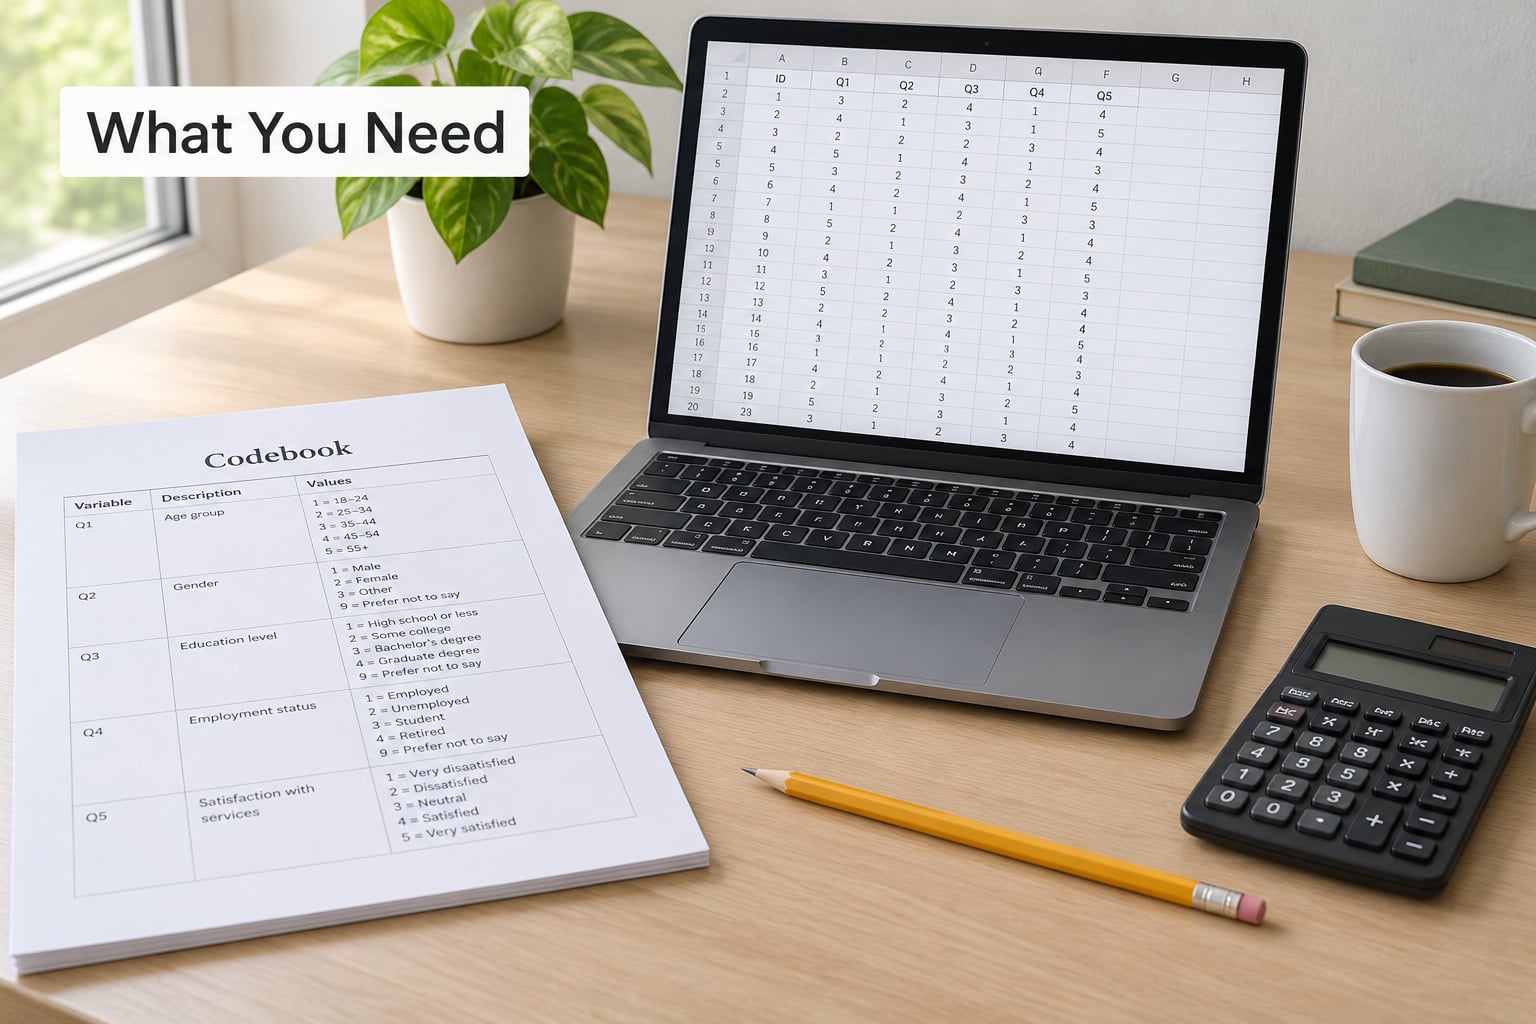
You need the item-level dataset — one row per respondent, one column per question — plus the documentation that came with the instrument.
Specifically, get these four things ready first:
- The raw export, untouched. Keep the original file read-only and do your recoding on a copy. Every later step is easier to audit when you can diff against the original.
- The codebook or scoring manual. It tells you the exact response options, which items are reverse-worded, and whether any items should be excluded from the total. Guessing the minimum and maximum values is the most common source of a wrong composite.
- A written scoring rule. Decide the sum or mean, the minimum number of items a respondent must answer, and how partial responders are handled before you look at any results. Deciding after seeing alpha or correlations is how people end up with rules that fit their noise.
- Software. SPSS, R, Stata, Excel or Google Sheets all work. Excel is genuinely fine for a small dataset with a fixed item list; the moment items get added or removed you will want something reproducible.
A syntax file that builds the composite from scratch is worth ten minutes of setup. It means a corrected item list takes one edit rather than a re-clicking session.
How to Create Composite Scores from Survey Items
A composite score reduces many responses to one value by applying a fixed arithmetic rule to items that measure the same construct — the satisfaction items, the burnout items, the ten knowledge questions.
Four terms get used interchangeably, and the confusion causes real mistakes:
- Sum (total score). The raw addition of every item. Range is the sum of the item ranges, so 8 items on a 1–5 scale run from 8 to 40.
- Mean score. The same information divided by the number of items. Range stays on the original scale, usually 1 to 5, which is what most published scale scores use.
- Index. A composite assembled from variables that are not all on the same scale or do not all measure one construct, such as a health risk index combining blood pressure, cholesterol and a smoking score. Indices are usually standardized first precisely because the inputs are incomparable.
- Factor score. A composite built from a data-driven estimate of how items cluster, weighted by loadings rather than equally.
One naming trap worth flagging: naming a variable “scale” in SPSS Variable View, or setting Measure to Scale, changes nothing about the data. Measure to Scale is a display hint. A single item on a 1–5 Likert response format still contains five distinct values, and a composite built from eight such items can be treated as continuous for most analyses only because the sum has more distinct values.
There are three practical routes. The equally weighted mean or sum covers the large majority of survey work. A weighted or standardized composite is for cases where items have different spreads or different theoretical importance. A factor score is for when you want the weights estimated from the data rather than set by the instrument designer.
Step-by-Step
Step 1: Identify the Items That Belong Together
Items belong together when they measure the same construct substantively, not because they share a response format.
Read the wording of each item and write the construct it is supposed to tap. Items that measure attention or social desirability, or that mix two ideas in one sentence, usually break the group. Then confirm all the items use the same response options — a 1–5 item cannot be summed with a 0–10 item without first converting both to a common basis.
Finally, note the direction of each item. Positively worded items such as “I feel supported by my supervisor” run one way; negatively worded ones such as “I feel unsupported by my supervisor” run the other, and they have to be flipped before anything is added up.
How to tell it worked: you can state the construct in one sentence and map every item in the set to that sentence. If one item cannot be mapped without hedging, it probably belongs in a different analysis.
Step 2: Check and Prepare the Survey Data
Run a frequency table on every item before combining anything, and read the value labels rather than trusting the column header.
Look for four things. Values outside the documented range usually mean a data-entry slip or an “other” option that was never coded. Zeroes and 99s in a 1–5 item are missing codes, not real answers, and must be declared as missing in the software rather than left as numbers. Blank cells can mean “skipped” or “not shown”, and those need different handling. Long strings of a single response at the extreme usually mean straight-lining rather than a strong opinion.
Rename variables to something short and unambiguous — q1, q2, q10 rather than a mix of abbreviations — and set the display decimals so two items with different decimal places do not create false precision in the total.
How to tell it worked: every frequency table shows only documented values, minimum and maximum match the codebook, and the missing count per item is something you have written down.
Step 3: Choose the Scoring Method
Pick the method that matches your measurement, not the one that gives the prettiest result.
| Method | When to use it | How to read the result |
|---|---|---|
| Sum (total score) | All items share one response format and you want maximum precision | Range is the sum of item ranges, e.g. 8–40 for 8 items on a 1–5 scale |
| Mean | The same, but you want a score that stays on the original scale | Range matches the item range, e.g. 1 to 5 |
| Standardized (z) composite | Items have very different spreads, or you are adding items from different scales | Mean 0, standard deviation 1; interpret in standard deviations, not points |
| Weighted composite | Sub-scales have unequal reliability or unequal theoretical importance | Reflects the weights you set, so always report them |
| Factor score | You want weights estimated from the data rather than chosen in advance | Requires a defensible factor solution first |
The detail that surprises most people: an unweighted sum is not unweighted at all. Because each item contributes its own standard deviation to the total’s variance, an item that varies twice as much as its neighbours is silently doing twice as much work. Standardizing each item to a z-score before summing removes that hidden weighting.
How to tell it worked: you can state the method, the range and the interpretation in one sentence, and that sentence belongs in your methods section.
Step 4: Reverse-Code Items With Opposite Wording
Reverse-coding is the step most often skipped, and skipping it produces a low alpha, a strange factor solution and a score pointing the wrong way.
The formula is simple: (maximum scale value + minimum scale value) − original response. On a 1–5 scale that is 6 minus the response.
| Original | On a 1–5 scale | On a 1–7 scale | On a 0–10 scale |
|---|---|---|---|
| 1 | 5 | 7 | 10 |
| 2 | 4 | 6 | 9 |
| 3 | 3 | 5 | 8 |
| 4 | 2 | 4 | 7 |
| 5 | 1 | 3 | 6 |
| 6 | n/a | 2 | 5 |
| 7 | n/a | 1 | 4 |
In SPSS, use Transform > Reverse Code into Different Variables, select the negatively worded items, give them new names, and run the dialog. In syntax the same thing is:
RECODE q4 q7 (1=5) (2=4) (3=3) (4=2) (5=1) (SYSMIS=SYSMIS) (MISSING=MISSING)
INTO q4r q7r.
VARIABLE LABELS q4r 'Reversed' q7r 'Reversed'.
Always code into new variables. Overwriting the original removes your ability to check your work and to show a supervisor what changed.
How to tell it worked: compare the frequency table of q4 with q4r. The distribution should mirror exactly, and the minimum and maximum should be swapped.
Step 5: Calculate the Composite Score
The core formula is an arithmetic mean across the prepared items, with a stated rule for respondents who skipped some of them. This is the step where most of the actual work of how to create composite scores from survey items happens, and it is the one people rush.
Consider eight items on a 1–5 scale, q4 and q7 reverse-worded. One respondent gives q1=4, q2=5, q3=3, q4=2, q5=4, q6=5, q7=1, q8=3. After reverse-coding, q4 becomes (5+1)−2 = 4 and q7 becomes (5+1)−1 = 5. The prepared values are 4, 5, 3, 4, 4, 5, 5, 3.
The sum is 33, out of a possible 40. The mean is 33 ÷ 8 = 4.13, which sits on the original 1–5 scale and is the version most journals expect.
Now the missing-data rule. The common choice is a minimum-complete rule: compute the mean only if at least a set number of items were answered, say 6 of 8, and set the rest to missing otherwise. This is what SPSS’s MEANS() function does when you supply the minimum as its last argument.
COMPUTE comp_mean = MEANS(q1 q2 q3 q4r q5 q6 q7r q8, 6).
COMPUTE comp_total = SUM(q1 q2 q3 q4r q5 q6 q7r q8).
VARIABLE LABELS comp_mean 'Mean of 8 items, min 6 answered' comp_total 'Sum of 8 items'.
EXECUTE.
The same composite in R:
items <- c("q1","q2","q3","q4r","q5","q6","q7r","q8")
d$comp_total <- rowSums(d[items], na.rm = TRUE)
enough <- rowSums(!is.na(d[items])) >= 6
d$comp_mean <- ifelse(enough, rowMeans(as.matrix(d[items]), na.rm = TRUE), NA)
In Stata:
egen long comp_mean = rowmean(q1 q2 q3 q4r q5 q6 q7r q8), min(6)
egen long comp_total = rowtotal(q1 q2 q3 q4r q5 q6 q7r q8), min(6)
In Excel or Google Sheets, with the items in B2 to I2:
=IF(COUNT(B2:I2)>=6, AVERAGE(B2:I2), "")
=IF(COUNT(B2:I2)>=6, SUM(B2:I2), "")
One warning about Excel: SUM ignores text and blanks silently, so a column holding the string “NA” instead of a real missing marker will quietly distort the total. Either leave genuinely empty cells or use SUMPRODUCT with an ISNUMBER test.
How to tell it worked: check the new variable’s minimum and maximum against the theoretical range, and count how many respondents fell outside your minimum-complete rule.
Step 6: Standardize the Score When Comparing Scales
Standardize when items have noticeably different spreads, when you are pooling items from different instruments, or when you want each construct to contribute equally to a larger index.
The conversion is (raw value − mean) ÷ standard deviation. If q1 has a mean of 3.8 and a standard deviation of 1.1, a response of 5 becomes (5 − 3.8) ÷ 1.1 = 1.09, or roughly one standard deviation above average.
Summing those z-scores across items gives a composite with a mean of exactly 0 and a standard deviation of 1, so a score of 1.4 means 1.4 standard deviations above the sample mean. That is the composite most often called a composite z score.
How to tell it worked: the standardized composite should have a mean of 0 and a standard deviation of 1, and no item should contribute more variance than another unless you wanted that deliberately.
Step 7: Check Reliability and Validity
Internal consistency tells you whether the items behave as though they come from a single source; it does not tell you that they measure the thing you claim.
Cronbach’s alpha is the standard check. It compares the variance of the total score to the sum of the item variances:
α = (k ÷ (k − 1)) × (1 − Σs²ᵢ ÷ s²ₜ)
where k is the number of items, s²ᵢ is each item’s variance, and s²ₜ is the variance of the total. With k items, alpha rises as average inter-item correlation rises and drops as the item count falls, so a short scale with modest correlations can look unreliable on arithmetic alone.
In SPSS the path is Analyze > Scale > Reliability Analysis, move the prepared items in, set Scale to Alpha, and read two columns in the output: corrected item-total correlation and alpha if item deleted.
RELIABILITY /VARIABLES=q1 q2 q3 q4r q5 q6 q7r q8
  /SCALE('ALL VARIABLES') ALL
  /SUMMARY=TOTAL MEANS VARIANCE
  /STATISTICS=DESCRIPTIVE SCALE CORR.
  /MISSING=LISTWISE.
How to read the output. Alpha above .70 is usually acceptable for research, above .80 for a score used to make decisions about people, and above .90 suggests items are near-duplicates. A corrected item-total correlation below .30 means that item is not pulling in the same direction, and anything negative almost always points to an un-reverse-coded item or an item that measures something else.
Read “alpha if item deleted” as a diagnostic, not a shopping list. Deleting items to raise alpha changes the instrument and usually invalidates published norms or prior comparisons, which is why the reflex to prune is so costly. Check for a missed reverse-code first, then examine the item’s wording.
Two alternatives are worth knowing. McDonald’s omega estimates reliability from a factor model and performs better than alpha when items load unevenly or the scale is short. Composite reliability, CR = (Σλ)² ÷ ((Σλ)² + Σθ), comes from confirmatory factor analysis and is the right choice when you already have a measurement model. Neither replaces checking that the items cover the construct.
How to tell it worked: alpha sits where you need it, no item-total correlation is negative, and a single-factor check supports the assumption that the items hang together.
Step 8: Interpret and Report the Composite Score
Interpretation starts with the range: state the theoretical minimum and maximum, then the observed minimum and maximum, then the direction of the score.
For the eight-item example above, the theoretical range is 8 to 40 for the sum and 1 to 5 for the mean. An observed range of 9 to 40 is normal. An observed maximum of 47 means something went wrong in the coding, not that your sample was enthusiastic.
Say explicitly which direction is which. “Higher scores indicate greater burnout” prevents a reader from assuming the opposite, which matters because item direction is often reversed relative to the label people expect.
Then look at the distribution and outliers. A histogram that is heavily bimodal suggests the items may not be one scale. Extreme composite values are usually worth examining case by case rather than deleting automatically.
If the distribution is strongly skewed, many analysts report the median and interquartile range alongside the mean, and some convert the sum to a 0–100 scale with (raw − minimum) ÷ (maximum − minimum) × 100, which makes results easier to compare across instruments.
A copy-ready methods sentence:
A composite score was computed as the mean of the eight items, with negatively worded items (q4, q7) reverse-coded using the (5 + 1) − original transformation and a minimum of six valid item responses required. Internal consistency was good (Cronbach’s alpha = .82). Higher scores indicate greater burnout.
How to tell it worked: someone who has never seen your dataset could recompute the same number from your written rule.
Common Mistakes
These come up in almost every methods help forum and every statistics course using Likert data.
- Summing before reverse-coding. The classic failure. The fix is to reverse-code in Step 4 and confirm with a frequency comparison before running anything else.
- Combining items because they share a response format. Matching 1–5 labels does not make items part of one construct. Group by content, then check with alpha.
- Deleting items to raise alpha. This changes what you are measuring. Diagnose first: check reverse-coding, then item wording, then whether the scale was never unidimensional.
- Ignoring missing values. Sum ignores blanks and treats coded 9s as real numbers. Declare missing codes, then apply the minimum-complete rule you stated in advance.
- Reading alpha as proof of validity. A high alpha only means the items correlate. It says nothing about whether they measure the construct you named.
- Assuming an equal-weight sum is unweighted. Items with larger standard deviations contribute more. Standardize first if that is not what you want.
- Reporting a score with no range or direction. Always state the theoretical range, the observed range, the minimum-item rule and which direction means more of the construct.
One more worth naming: some researchers avoid composites entirely and use MANOVA or multivariate regression, keeping the items separate. That is a legitimate choice, particularly with few items or a large predictor set, but it changes what your results section can report. Decide deliberately rather than by default.
Frequently Asked Questions
How do I calculate a composite score in SPSS?
Prepare the items first, then run Transform u0026gt; Compute Variable, paste your prepared variables into the Numeric Expression box and use SUM() for a total or MEANS() for a mean. Put the minimum number of required items as the last argument, for example MEANS(q1 q2 q3 q4r, 6), which returns missing when fewer than six items were answered. Check the new variable’s range against the theoretical range before analysing.
What is a composite z score?
A composite z score is a combined score whose items were each converted to standard scores before being added. Each item becomes (raw value minus its mean) divided by its standard deviation, and the resulting composite has a mean of 0 and a standard deviation of 1. It is useful when items have different spreads or come from different instruments, and it is read in standard deviations rather than scale points.
How do I reverse score a Likert scale?
Use the formula (maximum scale value plus minimum scale value) minus the original response. On a 1 to 5 Likert scale that is 6 minus the answer, so 1 becomes 5, 2 becomes 4, 3 stays 3, 4 becomes 2 and 5 becomes 1. In SPSS use Transform u0026gt; Reverse Code into Different Variables and code into new variables so the originals stay available. Always check the frequency table afterwards to confirm the mirror pattern.
How do I interpret a composite score?
Start with the range. For eight items on a 1 to 5 scale, a sum runs from 8 to 40 and a mean from 1 to 5. Compare your observed minimum and maximum with those bounds, state which direction indicates more of the construct, and report the mean with a standard deviation or the median with an interquartile range if the distribution is skewed. Your methods section needs the scoring rule, the minimum-item rule and the interpretation direction.
Is composite reliability the same as Cronbach’s alpha?
No. They are related but not interchangeable. Cronbach’s alpha assumes items are tau-equivalent, contributing equally to true score. Composite reliability comes from a measurement model and uses factor loadings, so it accounts for uneven loadings, and it usually runs higher. With short scales or items of varying quality, omega and composite reliability give a fairer picture. Both still measure internal consistency only, not validity.
Why is my Cronbach’s alpha low?
Look at the corrected item-total correlations first. A negative correlation almost always means an item was never reverse-coded, or that it measures a different construct from the rest. A low but positive correlation under .30 points to vague, double-barrelled or off-construct wording. Check that every item uses the same response format, that stray codes are declared missing, and remember that very short scales have a low alpha ceiling regardless of item quality.
Conclusion
Four actions get you most of the way: confirm the items measure one construct, align their direction by reverse-coding anything negatively worded, apply one arithmetic rule with a stated missing-item threshold, then check reliability before you trust the result.
Most people who search how to create composite scores from survey items stop after the calculation. Write the scoring rule into your methods section instead, and update it whenever the item list changes. A composite score is only reproducible if someone else can rebuild it from what you wrote down.