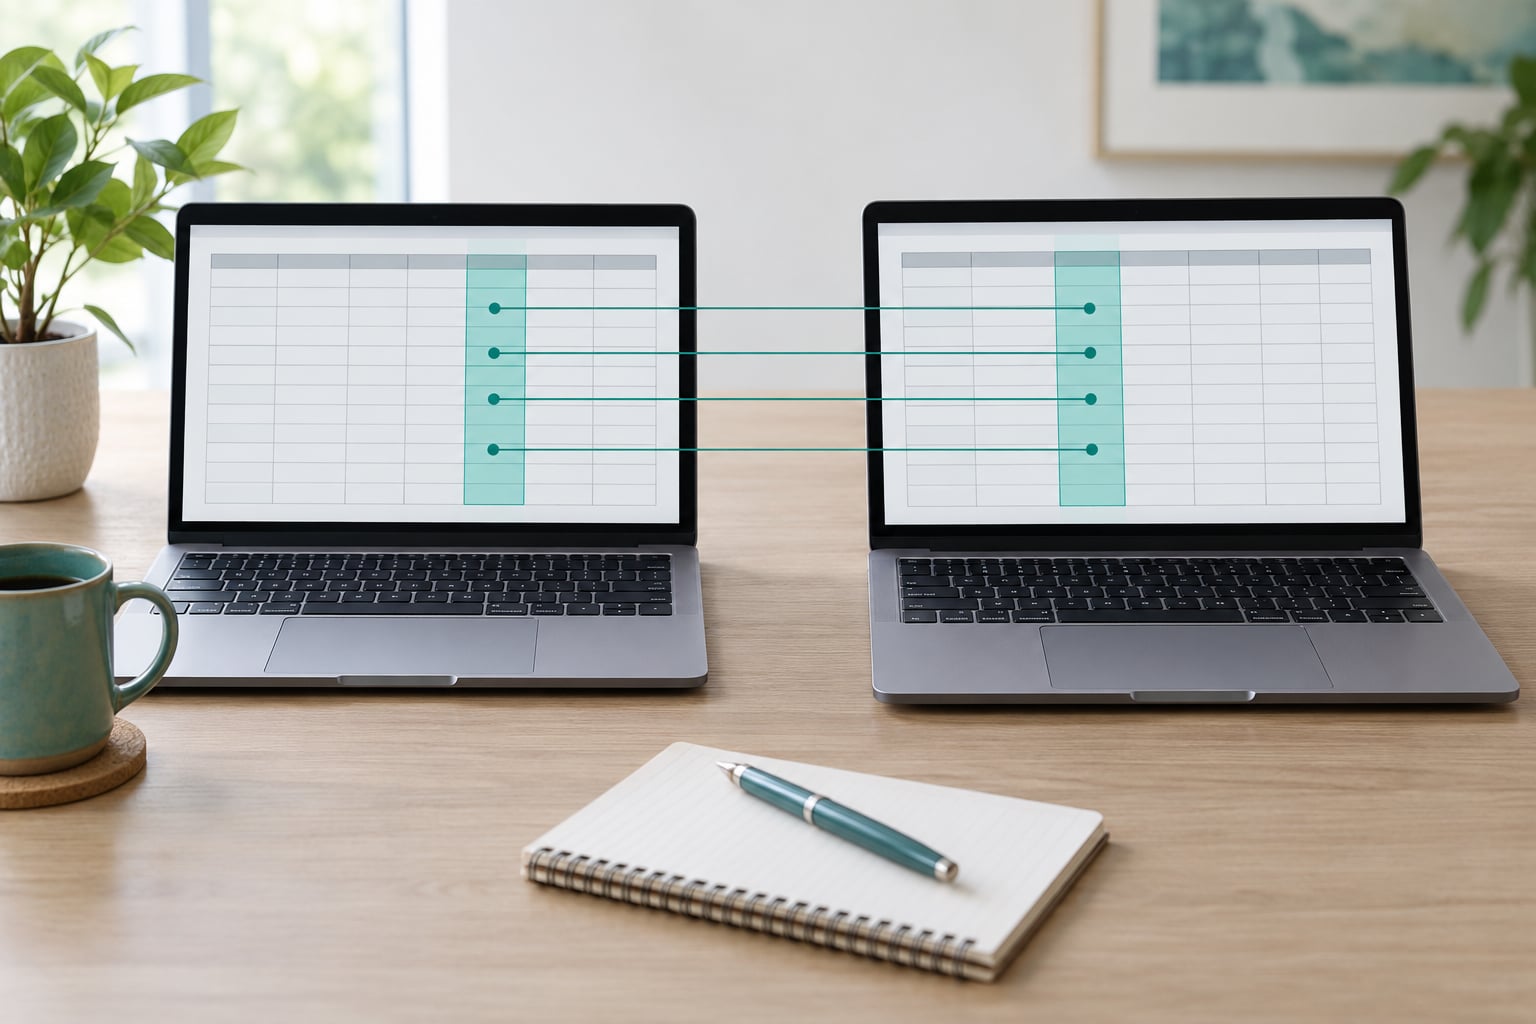
Merging two datasets by ID means matching the rows of both files on a shared unique identifier column, then combining their columns side by side so each record in the first file picks up attributes from the second. Every tool does it the same way under different names: merge in SPSS and Stata, merge() and left_join() in R. Ten minutes of checking before the merge saves an afternoon of chasing missing rows afterwards.
One decision comes first. If the two files describe the same people, sites or samples with different attributes, you are merging: rows stay put and columns are added. If they describe the same variables measured on different units or in different periods, you are appending: columns stay put and rows are added.
This guide walks through the whole workflow — checking the key, picking the join type, running the merge in SPSS, R or Stata, and validating the result — with the checks that catch duplicate IDs and unmatched records before they quietly distort your analysis.
Table of Contents
- 1What You Need
- 2Step-by-Step
- 3Step 1: Inspect and Standardize the ID Variable
- 4Step 2: Choose the Correct Join Type
- 5Step 3: Merge Two Datasets by ID in SPSS
- 6Step 4: Merge Two Datasets by ID in R
- 7Step 5: Merge Two Datasets by ID in Stata
- 8Step 6: Validate the Merged Data
- 9Common Mistakes
- 10Frequently Asked Questions
- 11How do I merge two datasets by ID?
- 12Why did my merge create more rows than it should?
- 13How do I find records that did not match?
- 14Do I need to sort the data before merging?
- 15Can I merge more than two datasets at once?
- 16How do I merge when the ID columns have different names?
- 17Conclusion
What You Need
Before you open any software, confirm these five things.
- Two datasets that belong together. Usually one is your analysis file and the other is a lookup or enrichment file.
- One shared ID variable present in both files. It does not have to share a name —
idin one file andclient_codein the other is fine as long as you point the merge at both. - The same data type in both files for that ID. Numeric in one and text in the other is the single most common reason a merge returns zero matches.
- A unique ID in at least one of the files. The ID can repeat in one file (one-to-many), but if it repeats in both, your row counts will multiply.
- A backup copy of both originals, and a test copy to merge into.
Also decide the match type you need: one-to-one (one row per ID on both sides), one-to-many (many rows in the second file per ID in the first), many-to-one, or many-to-many. If you cannot say which one you have, run the duplicate check in Step 1 rather than guessing.
Step-by-Step
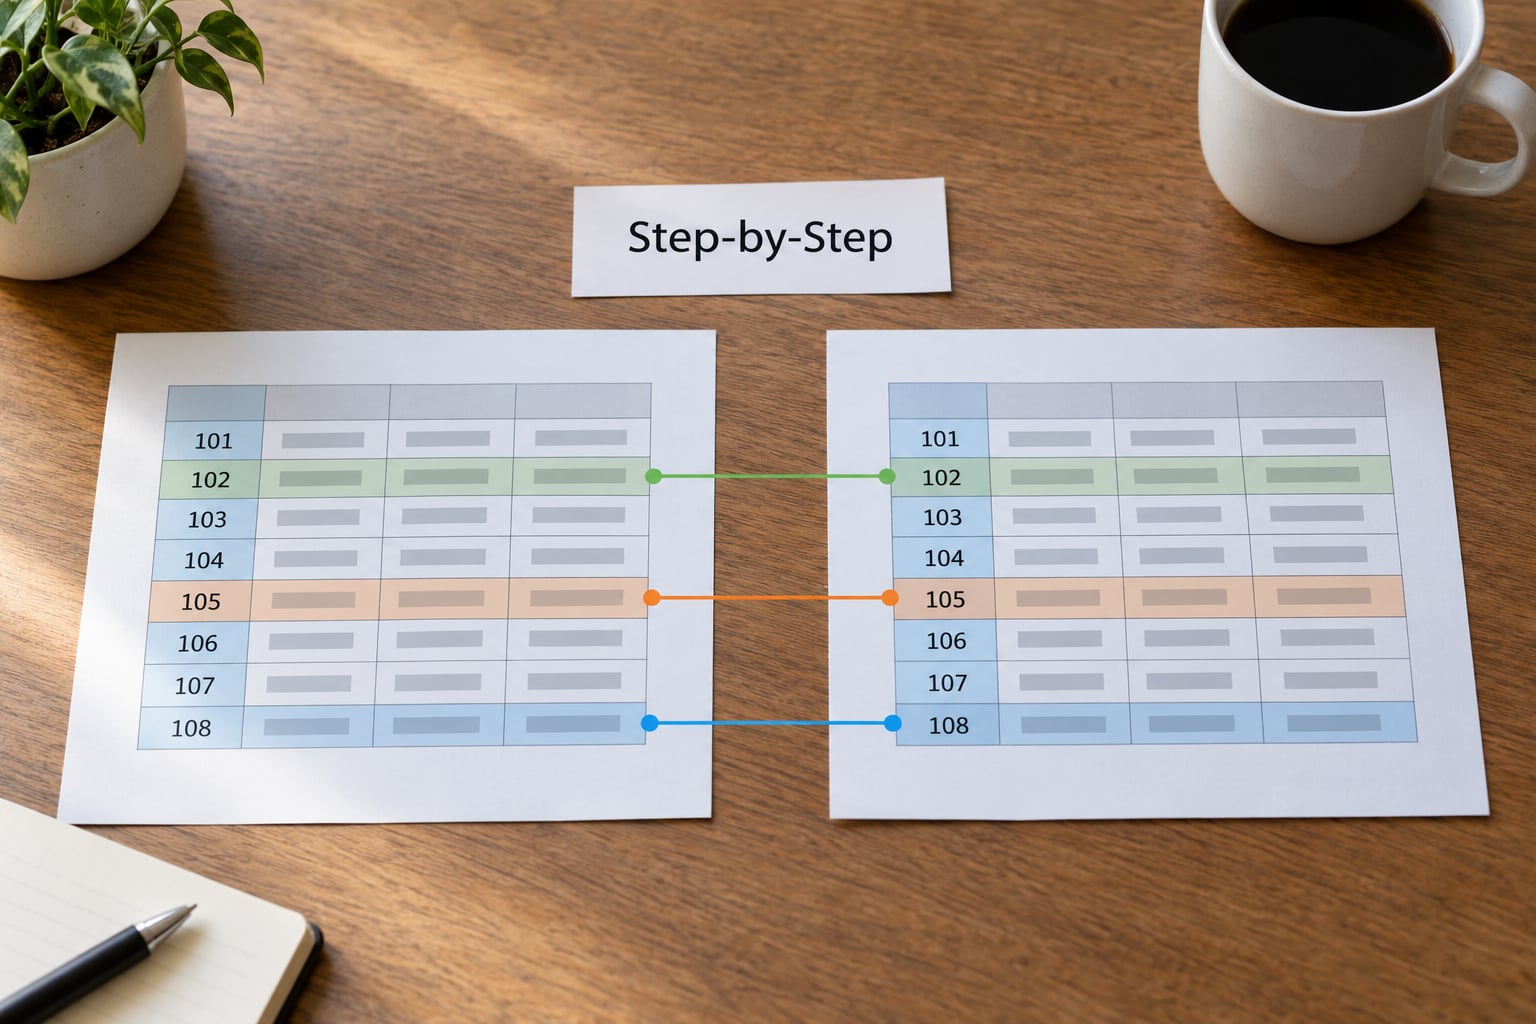
Step 1: Inspect and Standardize the ID Variable
Check the key column in both files before anything else, because every later problem traces back to it. You are looking for four things: missing values, duplicates, hidden whitespace, and inconsistent types.
In R, duplicated() and anyNA() give you the answer in one line each:
sum(duplicated(dat1$id))   # how many IDs repeat in the first file
sum(dat1$id %in% dat2$id)  # how many IDs from file 1 exist in file 2
table(dat1$id)              # frequency of every ID
In Stata, isid tells you outright whether the ID is unique:
isid id
duplicates report id
count if missing(id)
In SPSS, run Data > Compare Cases > Cases with the ID as the defining variable to list duplicates, or Transform > Compute Variable to build a frequency count you can inspect.
Whitespace and type problems are harder to see. Text IDs pulled from a spreadsheet often carry a trailing space or a leading zero that vanishes the moment the file is read as numbers, so 007 and 7 stop matching. Strip whitespace in R with trimws(as.character(dat1$id)), and if the ID must keep its leading zeros, read it in as character in Stata (infix or a string type) and in SPSS via File > Import Data > Text, where the variable type is set to String.
Fix the ID first, then merge. Every fix you skip here becomes a silent drop or a silent duplicate later.
Step 2: Choose the Correct Join Type
Join type decides which rows survive. Get this wrong and the merge either discards records or invents them, and the default in most software (inner) is the one that discards without telling you.
| Join type | Rows kept | Unmatched records | Typical research use |
|---|---|---|---|
| Inner | Only IDs found in both files | Silently dropped | Both files should describe the same population |
| Left | All rows from the first file | Kept, with empty values from the second file | Enriching your main analysis file with optional attributes |
| Right | All rows from the second file | Kept, with empty values from the first file | Rarely used; the reverse of a left join |
| Full outer | Every row from both files | Kept, with empty values on the other side | Comparing quarterly files where IDs were added or removed |
For most research files, left join is the safe default: it never deletes a record you already have. If your analysis population is defined by the first file, a left join keeps that population intact even when the second file is incomplete.
The second decision is merge versus append, and it is not a style preference:
| Operation | What changes | Row count after | Use when |
|---|---|---|---|
| Merge (join) | Columns are added | Same as the first file, or larger | Adding attributes to existing records |
| Append (concat, stack) | Rows are added | Sum of both files | Combining waves, sites or quarters |
People ask whether they need to transpose before merging. You do not — you never transpose. If your data has one row and hundreds of variable-named columns, that is a reshape problem, and merging will not fix it. Reshape it to long form first, then join on the common key.
Step 3: Merge Two Datasets by ID in SPSS
SPSS joins on sorted files by default, so the key has to be in ascending order in both datasets. Sort id ascending in each file first and confirm both files use the same format.
Then take Data > Merge Files > Add Variables to attach columns from the lookup file to your active dataset. On the first screen choose One-to-one (Cases matched by key) when the ID is unique in both files, or One-to-many (Unmatched cases from the active file) when the second file has repeated IDs. The one-to-many option keeps every row of the active file and appends only matching rows from the lookup file, which is SPSS’s version of a left join.
Next, move the ID variable into the key variables box using the arrow button. SPSS does not let you merge on an unnamed key. Tick Sort cases by key variables before merging if you have not sorted manually, then choose where the merged file goes: New dataset is safest because it leaves the original active file untouched.
Finally tick Flag unmatched cases and Flag cases with unmatched keys before you save. Those flags are your audit trail: filter on them afterwards to see exactly which records found no partner.
Read the output window before doing anything else. SPSS reports the number of cases read, the number of cases actually merged, and how many fell into each unmatched category. If the merged count is lower than the active file’s count, an inner one-to-one merge dropped records and you need to check the keys.
Step 4: Merge Two Datasets by ID in R
Base R’s merge() takes the same arguments the whole time. by handles matching names, by.x and by.y handle mismatched names, and all picks the join type.
# same ID name in both files
merge(dat1, dat2, by = "id", all.x = TRUE)

# different ID names
merge(dat1, dat2, by.x = "id", by.y = "client_code", all.x = TRUE)

# match status, in base R
merge(dat1, dat2, by = "id", all.x = TRUE, suffixes = c("_main", "_lookup"))
Use all.x = TRUE for a left join, all = TRUE for a full outer join, and no all argument for the default inner join. Adding sort = FALSE speeds up merges on large files.
The tidyverse route is clearer for auditing. dplyr tells you the relationship you are asserting, and errors if the data disagrees:
library(dplyr)

dat1 %>% left_join(dat2, by = "id", relationship = "one-to-many")

# IDs in the first file with no match in the second
anti_join(dat1, dat2, by = "id")

# same name in both files gets suffixed _x and _y
left_join(dat1, dat2, by = "id", suffix = c("_main", "_lookup"))
Pass relationship = "one-to-one" when the ID should be unique on both sides. If it is not, dplyr throws an error naming the offending key values, which is far kinder than getting a merged file with four times the rows. Use anti_join() to list unmatched IDs — that is the function most tutorials leave out.
For a worked check, count before and after:
nrow(dat1)                                   # 1200
nrow(left_join(dat1, dat2, by = "id"))        # 1200 or more
sum(!dat1$id %in% dat2$id)                    # unmatched in file 1
If the second number exceeds 1200, the ID repeats in dat2 and each repeat adds a row. Aggregate dat2 to one row per ID first.
Step 5: Merge Two Datasets by ID in Stata
Stata’s merge command is compact and it is the one that tells you exactly what happened, because it stores the outcome in the _merge variable.
isid id                      // confirms uniqueness; errors if not

merge 1:1 id using "lookup.dta"     // one-to-one
merge 1:m id using "lookup.dta"     // one-to-many
merge m:1 id using "lookup.dta"     // many-to-one
merge 1:1 id using "lookup.dta", keep(master match)
Always run isid id first on the using file when you declare 1:1. Stata will refuse the merge if the key is not unique, which turns a silent row explosion into an error message.
The keep() option decides which observations stay. keep(master match) is a left join, keep(match using) is a right join, keep(3) keeps only matched records, and keep(master match using) is a full outer join. If you omit keep(), Stata keeps everything and flags it.
On a name collision, the master dataset — the one open when you typed the command — is authoritative. Its value is kept and the using file’s value is discarded, which is the answer to a question that comes up on the Stata list constantly.
Check the result with a tabulation:
tab _merge          // 1 = master only, 2 = using only, 3 = matched
count if _merge == 3
You do not need to sort before merging; Stata sorts internally. You also do not need xtset unless the ID is the time index in panel data.
Step 6: Validate the Merged Data
Never move straight from the merge to the analysis. Six checks take two minutes and catch every problem described above.
- Compare row counts. Write down the count before the merge and after. A left or outer join should never reduce the row count; any increase tells you the key repeated on the using side.
- Count matches and non-matches. In SPSS use the unmatched flags, in R run
anti_join(), in Stata runtab _merge. Report the numbers, even when they look fine. - Rescan for duplicate IDs. Re-run
isid,duplicated()or the SPSS duplicate check on the merged file. If you expected one row per ID and now have more, stop and pre-aggregate. - Look for unexpected empties. Missing values in a variable that should be complete usually mean the key never matched, not that the data is genuinely absent.
- Confirm variable types. Check that measurement variables did not change from numeric to text during the merge.
- Check the unit of analysis. Confirm the merged row is still one person, one site or one transaction. If one ID has repeated rows on both sides, the merge produced a many-to-many cartesian result and your unit of analysis has changed.
Save the validation output somewhere. When someone asks why the totals differ from the source file three months later, the counts are the answer.
Common Mistakes
Leading zeros disappear. The text ID 007 was read as the number 7 in one file. Read the column as a string in both, then merge.
One ID is text, the other is numeric. SPSS and Stata both treat these as different values and you get an empty match set. Make them the same type before merging.
Trailing spaces. A copy-paste from a web form leaves a space at the end of every code. Strip it with TRIM in SPSS, trimws() in R, or trim() in Stata.
Duplicate IDs in the lookup file. This is the one that produces a higher total than the source, and Excel users hit it most often with VLOOKUP. If one ID appears three times in the second file, every row with that ID is duplicated. Group or aggregate the lookup file to one row per ID before joining.
Row counts balloon after the merge. Same cause, different symptom: a cartesian product where every key in file 1 matches several keys in file 2. Fix it with the duplicate check, not by deleting rows afterwards.
Rows disappear silently. That is an inner join doing exactly what you asked. Switch to a left join or full outer join, then audit the unmatched records.
You cannot find unmatched records. Use the flags: SPSS’s unmatched case flags, R’s anti_join(), Stata’s _merge == 1.
Two versions of a variable. When both files have the same non-key variable, R suffixes them _x and _y. Rename before merging (suffix = c("_main", "_lookup") or a manual rename in SPSS) so the names tell you which file each column came from.
Two key columns left over. When you merge with by.x and by.y, both key columns stay in the output. Drop the one you do not need.
Sorting as a ritual. SPSS needs sorted files; Stata and R do not. Sorting because a forum post said so wastes time, and an unsorted merge in SPSS silently misbehaves instead of warning you.
Overwriting the original. Write to a new file every time. Recovering a pre-merge dataset you overwrote is painful.
Frequently Asked Questions
How do I merge two datasets by ID?
Match the rows of both files on a shared identifier column so each record picks up attributes from the other. Check that the ID exists in both files, has the same data type, and is unique in at least one of them, then pick a join type. Inner keeps only matches, left keeps every row of the first file, and a full outer join keeps every row from both.
Why did my merge create more rows than it should?
Because the ID is not unique in the second file. Each extra row sharing that ID multiplies into the result, so three matches per ID turn 500 rows into 1,500. Check for duplicate IDs before merging and aggregate the lookup file to one row per ID first. In R use a relationship argument, in Stata run isid, in SPSS pick the one-to-many option rather than one-to-one.
How do I find records that did not match?
Every package gives you a way to list them. In SPSS, tick flag unmatched cases when you run the merge and filter on the resulting flag variable. In R, anti_join returns exactly the rows from the first file with no partner in the second. In Stata, the merge creates _merge, where 1 means master only and 2 means using only; count them with tab _merge.
Do I need to sort the data before merging?
Only in SPSS, which merges on sorted files and needs the key in ascending order in both datasets. Stata and R sort internally, so sorting first is optional there and costs a little time on large files. If a forum post told you sorting is required, that advice is specific to SPSS and does not transfer to the other tools.
Can I merge more than two datasets at once?
Yes, though the mechanics differ. In SQL, chain several JOIN clauses. In R, merge in sequence against an accumulating object, or use Reduce with a list of joins, checking the key after each step. In Stata, merge repeatedly with a using file and verify isid each time. In SPSS, nest the add variables operation by saving each merge to a new dataset before starting the next.
How do I merge when the ID columns have different names?
Rename one of them, or tell the software which column to match on each side. R takes by.x and by.y arguments, so merge takes by.x = ‘id’, by.y = ‘client_code’. In Stata, rename before merging or use the rename option on the using list. In SPSS the key variable is picked from a list, so mismatched names are not a problem as long as the values themselves are identical.
Conclusion
Five actions, in order, make most merges clean. Back up both files. Confirm the ID exists in both, is the same type, and is unique in at least one file. Choose the join type that matches your analysis population, usually left join. Merge into a new dataset or a test copy rather than overwriting anything. Then validate: compare row counts, count matched and unmatched records, rescan for duplicate IDs, and check that the merged row is still your unit of analysis.
That last check is the one people skip and the one that catches the most. If you have merged two datasets by ID and the result has more rows than the file you started with, the key was not unique on one side and the totals will be wrong until you aggregate it first.