Statistical power is the probability that a test correctly rejects a false null hypothesis, so how to run a power analysis before collecting data comes down to four numbers: the significance level, the power you want, the smallest effect worth detecting, and the outcome’s variability. Supply any three and the software solves for the fourth, which is the sample size you recruit for.
Done before collection, that number is a plan. Done afterwards, it is arithmetic on data you already have, and the usual reason a null result came out null is still unanswered. This guide walks through the whole sequence, names the free tools that do the arithmetic, and shows where researchers most often go wrong.
Most of this takes an afternoon, plus a conversation with your supervisor or a statistician if the design is unusual.
Table of Contents
- 1What You Need Before You Start a Power Analysis
- 2How to Run a Power Analysis Step by Step
- 31. Define the primary analysis and test
- 42. Set alpha, power, and the minimum effect size
- 53. Choose the appropriate power-analysis method
- 64. Calculate the required sample size
- 75. Adjust for design realities
- 86. Check assumptions and run sensitivity scenarios
- 97. Document and report the calculation
- 10Common Mistakes in Power Analysis
- 11Frequently Asked Questions
- 12What sample size should I use for a power analysis?
- 13Is 80% power always appropriate for a study?
- 14Can I use an effect size from a previous study?
- 15What is the difference between a priori and post hoc power analysis?
- 16How do I calculate power for a t-test, ANOVA, chi-square, or regression?
- 17Should I add extra participants for expected nonresponse?
- 18Conclusion
What You Need Before You Start a Power Analysis
You need four quantities, and a power analysis cannot run without three of them. Everything else on this list just makes the three easier to defend.
| Input | Typical value | What it controls | Where it comes from |
|---|---|---|---|
| Alpha (significance level) | 0.05 | False positive rate | Convention in your field, or a stricter value if you test several outcomes |
| Power (1 minus beta) | 0.80, sometimes 0.90 | False negative rate | A judgment about how costly a missed effect is for your project |
| Effect size | Varies by test | The size of the difference you want to detect | Prior literature, meta-analysis, pilot data, or an expert panel |
| Variance or standard deviation | Varies by outcome | The noise in your measurements | Pilot data, published values for your measure, or historical records |
You also need to know the shape of the design: independent groups or the same people measured twice, how many groups or predictors, whether the test is one-tailed or two-tailed, and roughly what share of recruited participants you expect to drop out before the final analysis.
Effect size is where most people stall. If you have nothing to go on, work through your sources in order: a meta-analysis of the same question, the most recent comparable primary studies, your own pilot data, and finally a panel of experts who state the smallest difference that would change practice. Write down where each number came, because a reviewer will ask and an unsourced effect size is the fastest way to lose their trust.
Fix the test before the inputs. A power analysis for the wrong statistical test is a precise answer to a question you are not asking.
How to Run a Power Analysis Step by Step
1. Define the primary analysis and test
Start with the one comparison your study exists to answer. Write down the outcome variable, the groups or predictor, and the exact test you plan to run, such as an independent samples t-test, a one-way ANOVA, or multiple regression.
Decide now whether you have one primary outcome or several. With one, keep alpha at 0.05. With four co-primary outcomes, you either split alpha across them or accept a 14% chance of at least one false positive, and that choice belongs in the protocol before data exists, not after.
2. Set alpha, power, and the minimum effect size
The four inputs are related, so specifying three determines the fourth. That is the whole trick behind the “specify any three, solve for the fourth” rule that gets repeated on Cross Validated and in methods courses.
Alpha of 0.05 is the field default, not a law. Power of 0.80 is the minimum most reviewers accept; 0.90 is defensible when a missed effect wastes a year or a large grant.
Effect size is not the same thing as statistical significance. A p-value below 0.05 says the result is unlikely under the null. It says nothing about how large the effect is or whether it matters, which is why the power analysis needs a substantive effect size, stated in the units your test expects.
Cohen’s benchmarks are a last resort, not a starting point. When you must use them, d of 0.2 is small, 0.5 is medium, and 0.8 is large. For ANOVA use f, for regression use f-squared, for proportions and chi-square use w.
3. Choose the appropriate power-analysis method
Three approaches exist, and only one of them is useful before you collect data.
An a priori power analysis sets inputs from theory and prior literature, then returns the sample size. A sensitivity analysis runs the same calculation across a range of plausible effect sizes and reports the range of sample sizes. A post hoc power analysis plugs in your observed effect size after the fact, which tells you almost nothing, because power is a function of the same effect that the test already evaluated.
Researchers on r/AskStatistics describe running post hoc power after a non-significant result and getting a high number, then misreading it as “the study was nearly powerful enough.” The real lesson is that the study was not powered to detect that effect. Fisher’s objection still stands: post hoc power from an observed effect is circular. If you have already collected data, report confidence intervals and the minimum detectable effect instead.
4. Calculate the required sample size
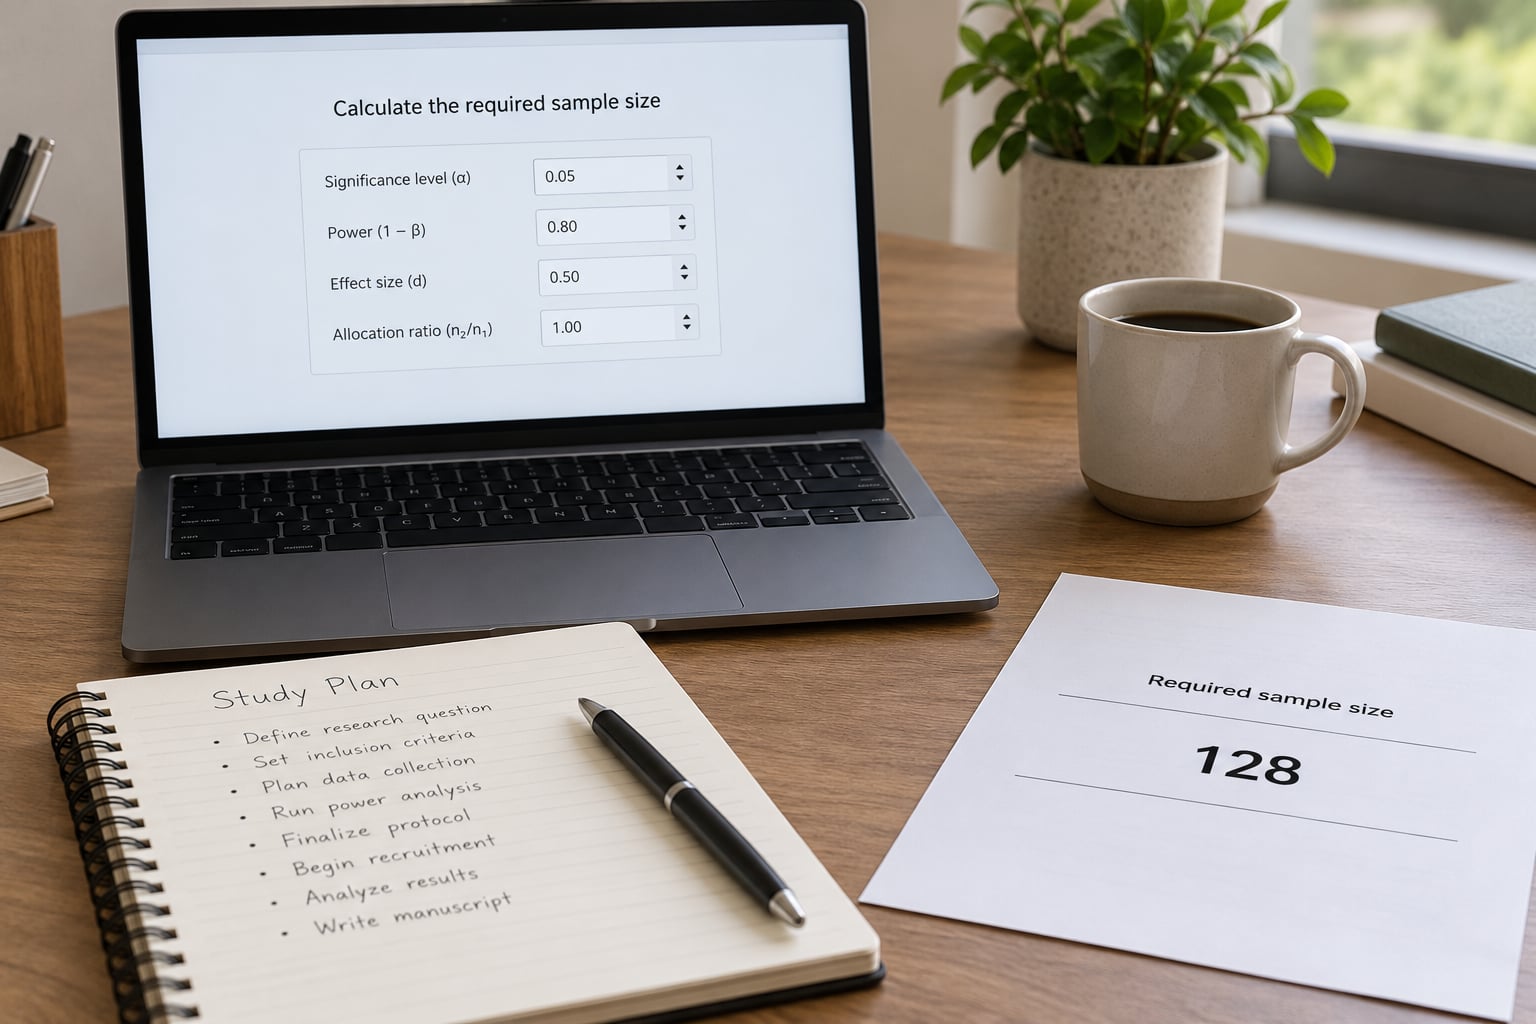
Pick a tool and enter the four inputs. Menu names shift a little between versions, so take a screenshot of what you typed.
| Tool | Cost | Learning curve | Best fit |
|---|---|---|---|
| G*Power | Free | Low, point and click | The default for most standard tests |
| R with the pwr package | Free | Medium | Reproducible scripts, effect size and power in one call |
| Python statsmodels | Free | Medium | Pipelines and simulation-based power |
| jamovi or JASP | Free | Low | Menu-driven work in SPSS or R syntax |
| Web calculators | Free | Very low | Quick checks, or documenting decisions for an IRB |
In G*Power, choose the a priori analysis tab, pick the test family that matches your design, enter alpha, power, and the effect size in standardized units, then set allocation ratio to 1 unless your groups differ in size. Hit calculate and read the total sample size, not just the per-group number.
The output matters as much as the number. G*Power draws a power curve showing how power climbs as the sample grows, and a dashed line marking your chosen alpha. Look at where your required n sits on that curve. If it sits on the steep part, small under-recruitment costs you a lot of power. If it sits on the flat part, you have bought very little with the extra participants.
Users on r/AskStatistics most often report picking the wrong test family or entering a raw score where a standardized effect size belongs. Fixing a wrong input is faster than fixing an un-recruitable sample size, so re-read every box before you accept the output.
5. Adjust for design realities
The raw output is an idealized number. Real studies lose participants and waste statistical independence.
| Adjustment | How it works | Typical value |
|---|---|---|
| Attrition | Divide required n by one minus the dropout rate | 10 to 20 percent, higher for longitudinal cohorts |
| Clustering | Multiply by the design effect, one plus average cluster size times ICC minus one | Depends entirely on your ICC |
| Multiplicity | Lower alpha per test, for example by Bonferroni, or plan a Tukey HSD for post hoc pairs | Alpha divided by the number of comparisons |
| Unequal groups | Set the allocation ratio in the software rather than splitting evenly by hand | 2 to 1 is common in recruitment-limited trials |
Multiply these adjustments in sequence rather than adding percentages, and check whether you can avoid one instead. More recruitment sites means more clustering, so a smaller number of better sites can protect your effective sample size.
A finite population correction matters only when your sample is a large share of the population, and applying it to a convenience sample where you could not have drawn the same people twice is a false economy. If that describes your study, ask a statistician before trimming the target.
6. Check assumptions and run sensitivity scenarios
One number implies more certainty than you have. Re-run the calculation at d of 0.2, 0.3, and 0.5 and write down all three sample sizes. Report the range alongside your chosen value and say why you chose it.
Then vary the other assumptions one at a time. What happens at 90% power? At a higher dropout rate? With a two-tailed rather than one-tailed test? If your conclusion flips on one of these changes, you have learned something real about how fragile the design is.
Power curves are worth reading directly here. Plot power against sample size for your effect sizes, mark the n you can realistically recruit, and see where that line crosses. Where it crosses below 0.80 is your risk, stated honestly.
Two situations call for simulation instead of a closed-form formula. Non-standard designs, such as complex mixed models or cluster randomized trials with time-to-event outcomes, and any study where the standard test is only an approximation. Practitioners in r/AskStatistics consistently recommend simulating under a plausible alternative when the design does not fit a menu option, and that advice holds.
7. Document and report the calculation
Write the calculation into your protocol now, while the reasoning is fresh. Your methods section should carry the test, the software and version, alpha, power, effect size with its source, any design assumptions, the attrition adjustment, and the final recruitment target.
A reviewer asking whether a statistical power analysis guided sample size estimation wants to check your logic, not admire your arithmetic. They are looking for a defensible effect size and a stated source, a power level their field accepts, a test that matches the design, and adjustments that account for what actually happens in the field.
Example: “An a priori power analysis for a two-independent-samples t-test was conducted in G*Power 3.1.9.8 to detect a small-to-medium standardized mean difference of d = 0.35, taken from the pooled estimate reported in three prior studies of comparable interventions. We set alpha to 0.05 (two-tailed) and power to 0.90, which requires 176 analyzable participants, 88 per arm. Allowing for 15% attrition, we recruited 208 participants in total.”
Pre-register the analysis plan and the sample size on the Open Science Framework so the target cannot quietly drift during recruitment. It costs ten minutes and answers the most common reviewer objection there is.
Common Mistakes in Power Analysis
Running the calculation after seeing the data. Post hoc power from an observed effect is circular. Report confidence intervals and the minimum detectable effect instead.
Copying Cohen’s benchmarks without reading the literature. d of 0.5 may be a big effect in one field and ordinary in another. Source the number or justify the benchmark.
Picking power before thinking about the cost of missing the effect. 0.80 is a floor. In a confirmatory trial with expensive follow-up, 0.90 justifies the extra recruitment.
Forgetting attrition. A 15% dropout rate on 200 recruits leaves 170, which may drop you under the target.
Using the wrong test family or the wrong effect-size measure. Paired designs need a paired test, and chi-square needs w, not d.
Ignoring clustering. People in the same family, classroom, or clinic are correlated, so your effective sample is smaller than your actual one.
Treating a single number as a guarantee. Power is conditional on inputs that are estimates. A range with stated assumptions is more honest and more defensible.
Believing rule-of-thumb sample sizes are power analyses. The common claims that 30 participants per group is enough, or that adding 10 percent covers nonresponse, ignore effect size, alpha, and power entirely. They survive as rough floors for large effects in exploratory work and fail for confirmatory studies. Calculate instead.
One more worth naming: small samples can produce significant results. Significance at a small n often means a very large observed effect, and with a wide confidence interval you may not know where the true effect sits. That is why power analysis and interval estimation belong in the same methods section.
Frequently Asked Questions
What sample size should I use for a power analysis?
There is no universal number, because the required sample size depends on your test, effect size, alpha, and power. A common two-group t-test detecting a medium effect at 80% power needs roughly 64 per group, while the same test for a small effect needs several hundred. That is why the question is never which number to use but which three of the four inputs you can defend.
Is 80% power always appropriate for a study?
Eighty percent is the minimum most journals and reviewers accept, and it is defensible for exploratory work and low-cost studies. It means a one in five chance of missing a real effect. For confirmatory trials, expensive interventions, or a single funded study period, 90% power is often the better target, though it raises the required sample noticeably.
Can I use an effect size from a previous study?
Yes, and it is the preferred source. Use a meta-analysis where one exists, otherwise the most recent comparable primary studies, and prefer the pooled estimate over a single striking result. Match the outcome measure and population as closely as you can, and cite the source in your methods section. Pilot data work too, though treat it as a weaker estimate.
What is the difference between a priori and post hoc power analysis?
An a priori analysis runs before data collection, using an effect size derived from theory or prior literature, and returns the sample size you need. A post hoc analysis runs after collection using the observed effect size, which is circular because the test already evaluated that same effect. If your data are already in, report confidence intervals and the minimum detectable effect instead.
How do I calculate power for a t-test, ANOVA, chi-square, or regression?
Enter the same four inputs into a tool, but pair the test with the effect size it expects. Independent and paired t-tests use Cohen’s d. One-way and factorial ANOVA use f, regression uses f-squared, and chi-square tests on proportions use w. G*Power, the R pwr package, Python statsmodels, jamovi, and JASP all handle these families and return the required n.
Should I add extra participants for expected nonresponse?
Yes. Divide the required analyzable sample by one minus your expected dropout rate. At 15 percent attrition, a requirement of 170 analyzable participants means recruiting 200. Use 10 percent for a short cross-sectional survey and a higher figure for a longitudinal cohort or a hard-to-reach population, and state the rate you used and where it came from.
Conclusion
Start by fixing your primary analysis and the test that goes with it, then set alpha, power, and a sourced minimum effect. Run the calculation in a free tool, apply the design adjustments your study actually needs, and record every assumption in your protocol before recruitment opens.
Working through how to run a power analysis before collecting data takes an afternoon and settles most of the questions a reviewer, an ethics committee, or your own supervisor will raise later. Assumptions written down in 2026 stay defensible years later, so keep them with the data.